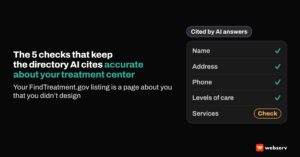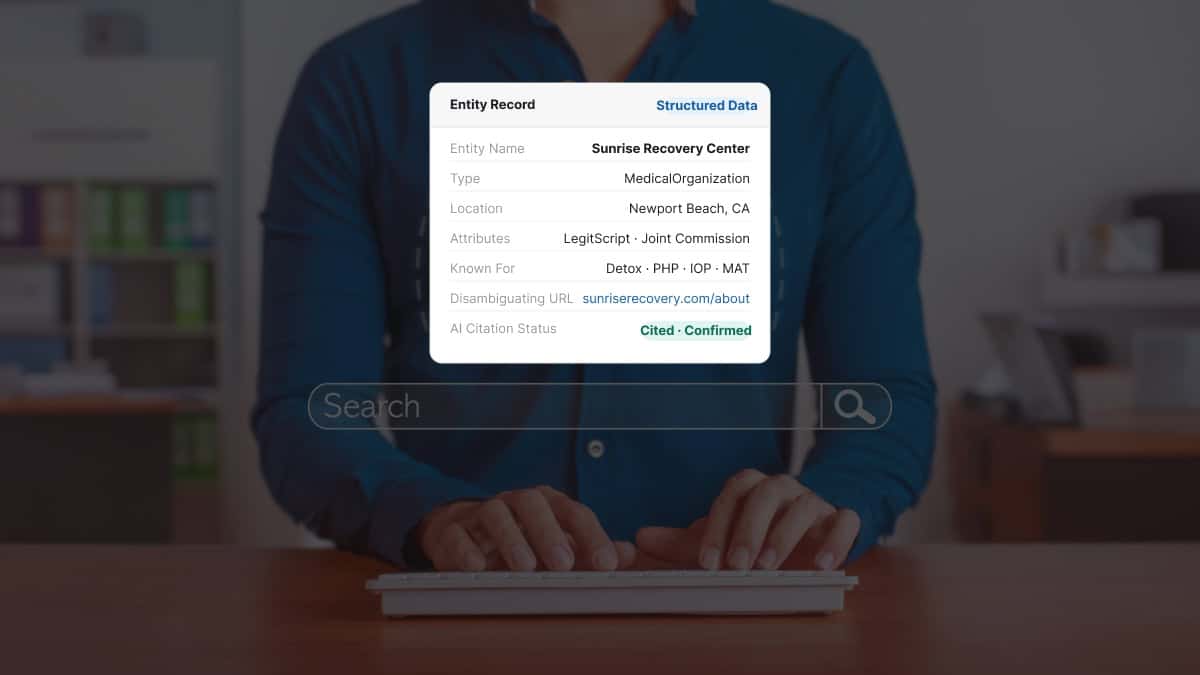
A 38-bed residential treatment center asked me last spring why their facility was never cited in ChatGPT or Google AI Mode answers, even though they had a strong site, real clinical depth, and 18 months of disciplined content publishing. I ran their site through three diagnostic checks.
The site had zero Organization schema deployed. The team had no Person schema for the clinical authors writing the blog. The “About” page named the executive director but did not link to any external authority profiles (LinkedIn, the Joint Commission Quality Check listing, Psychology Today).
And the Knowledge Graph showed no entity record for the facility at all. Google’s reasoning engine could not confidently identify what the facility was, where it operated, or what it specialized in.
We deployed an entity schema package over six weeks. Organization schema with knowsAbout declarations for the facility’s clinical specialties. LocalBusiness schema anchoring the facility to its physical address. Person schema for each clinical author with credentials and sameAs links to their professional profiles. MedicalClinic and MedicalSpecialty schema for the treatment programs.
Inside 90 days, the facility started appearing as a cited source in AI Mode answers for queries about residential treatment in their region, dual diagnosis care, and the specific modalities they specialize in. The content had been good the whole time. The retrieval layer had not been able to find it because nothing identified the facility as a known entity worth citing.
That gap is the entity SEO gap, and most behavioral health operators have it. The shift from keyword-based search to entity-based AI retrieval is the most consequential change in organic discovery since the mobile-first index.
The treatment centers that win in 2026 are the ones whose AEO program treats their organization, their clinicians, their services, and their locations as machine-readable entities, not as keyword targets. That entity infrastructure is what our AEO practice deploys first on every new client engagement.
Key Takeaways
- Entity SEO is the practice of optimizing for the entities (organizations, people, places, services, conditions) that search engines recognize in their Knowledge Graphs, rather than for keyword strings. Search has interpreted queries through entities since Google launched the Knowledge Graph in 2012, and AI search builds on that.
- Clear entity signals help search systems resolve who a source is. Google says structured data helps it understand page content, though no special schema is required to appear in AI Overviews or AI Mode.
- The
knowsAboutproperty is an underused way to state, in machine-readable form, the specific clinical and operational topics your organization covers. - Treatment centers need Organization, LocalBusiness, MedicalClinic, Person (for authors), and MedicalSpecialty schema deployed consistently across the site, plus
sameAslinks to authority profiles (LinkedIn, ASAM, Psychology Today, The Joint Commission). - Entity work pays off when content backs it up. Schema alone isn’t a citation lever: Ahrefs’ 2026 controlled test found adding schema produced no major lift in AI citations.
What Entity SEO actually is
Entity SEO is the discipline of optimizing for the conceptual entities that search engines and AI reasoning engines understand, instead of for the keyword strings users type. The shift sounds small. It is not.
A keyword-based search engine sees the query “residential treatment for opioid addiction in San Diego” as a string of words and tries to match those words to pages on the web.
An entity-based search engine sees the same query as a combination of three entities (residential treatment, opioid addiction, San Diego) plus the implicit fourth entity the user is asking for (a specific treatment provider). The engine then looks for sources that have established themselves as authoritative on each of those four entities and synthesizes the answer from those sources.
The implication is that ranking in 2026 is decreasingly a function of “does your page have the right keywords” and increasingly a function of “is your organization a recognized entity for the topics in this query.”
A page that targets the right keywords on a site with no entity recognition can lose the citation to a page on a site with stronger entity recognition, even if the keyword targeting is technically better.
This is the architecture Google has been building toward since the Knowledge Graph launched in 2012, and it sits on top of the broader AI Overview and ChatGPT citation environment that treatment centers now compete inside.
The Hummingbird update in 2013 introduced entity-driven query interpretation. BERT in 2019 added language model understanding of entity relationships. The 2024-2026 wave of generative AI search built the retrieval and reasoning layers on top of the entity foundation Google had been laying for a decade.
Treatment centers with clear, consistent entity signals give these systems less to guess about. Keyword targeting still matters, but it isn’t the whole picture.
How AI search engines actually use entities
The mechanism is worth understanding because it shapes what the optimization work looks like. Three stages matter.
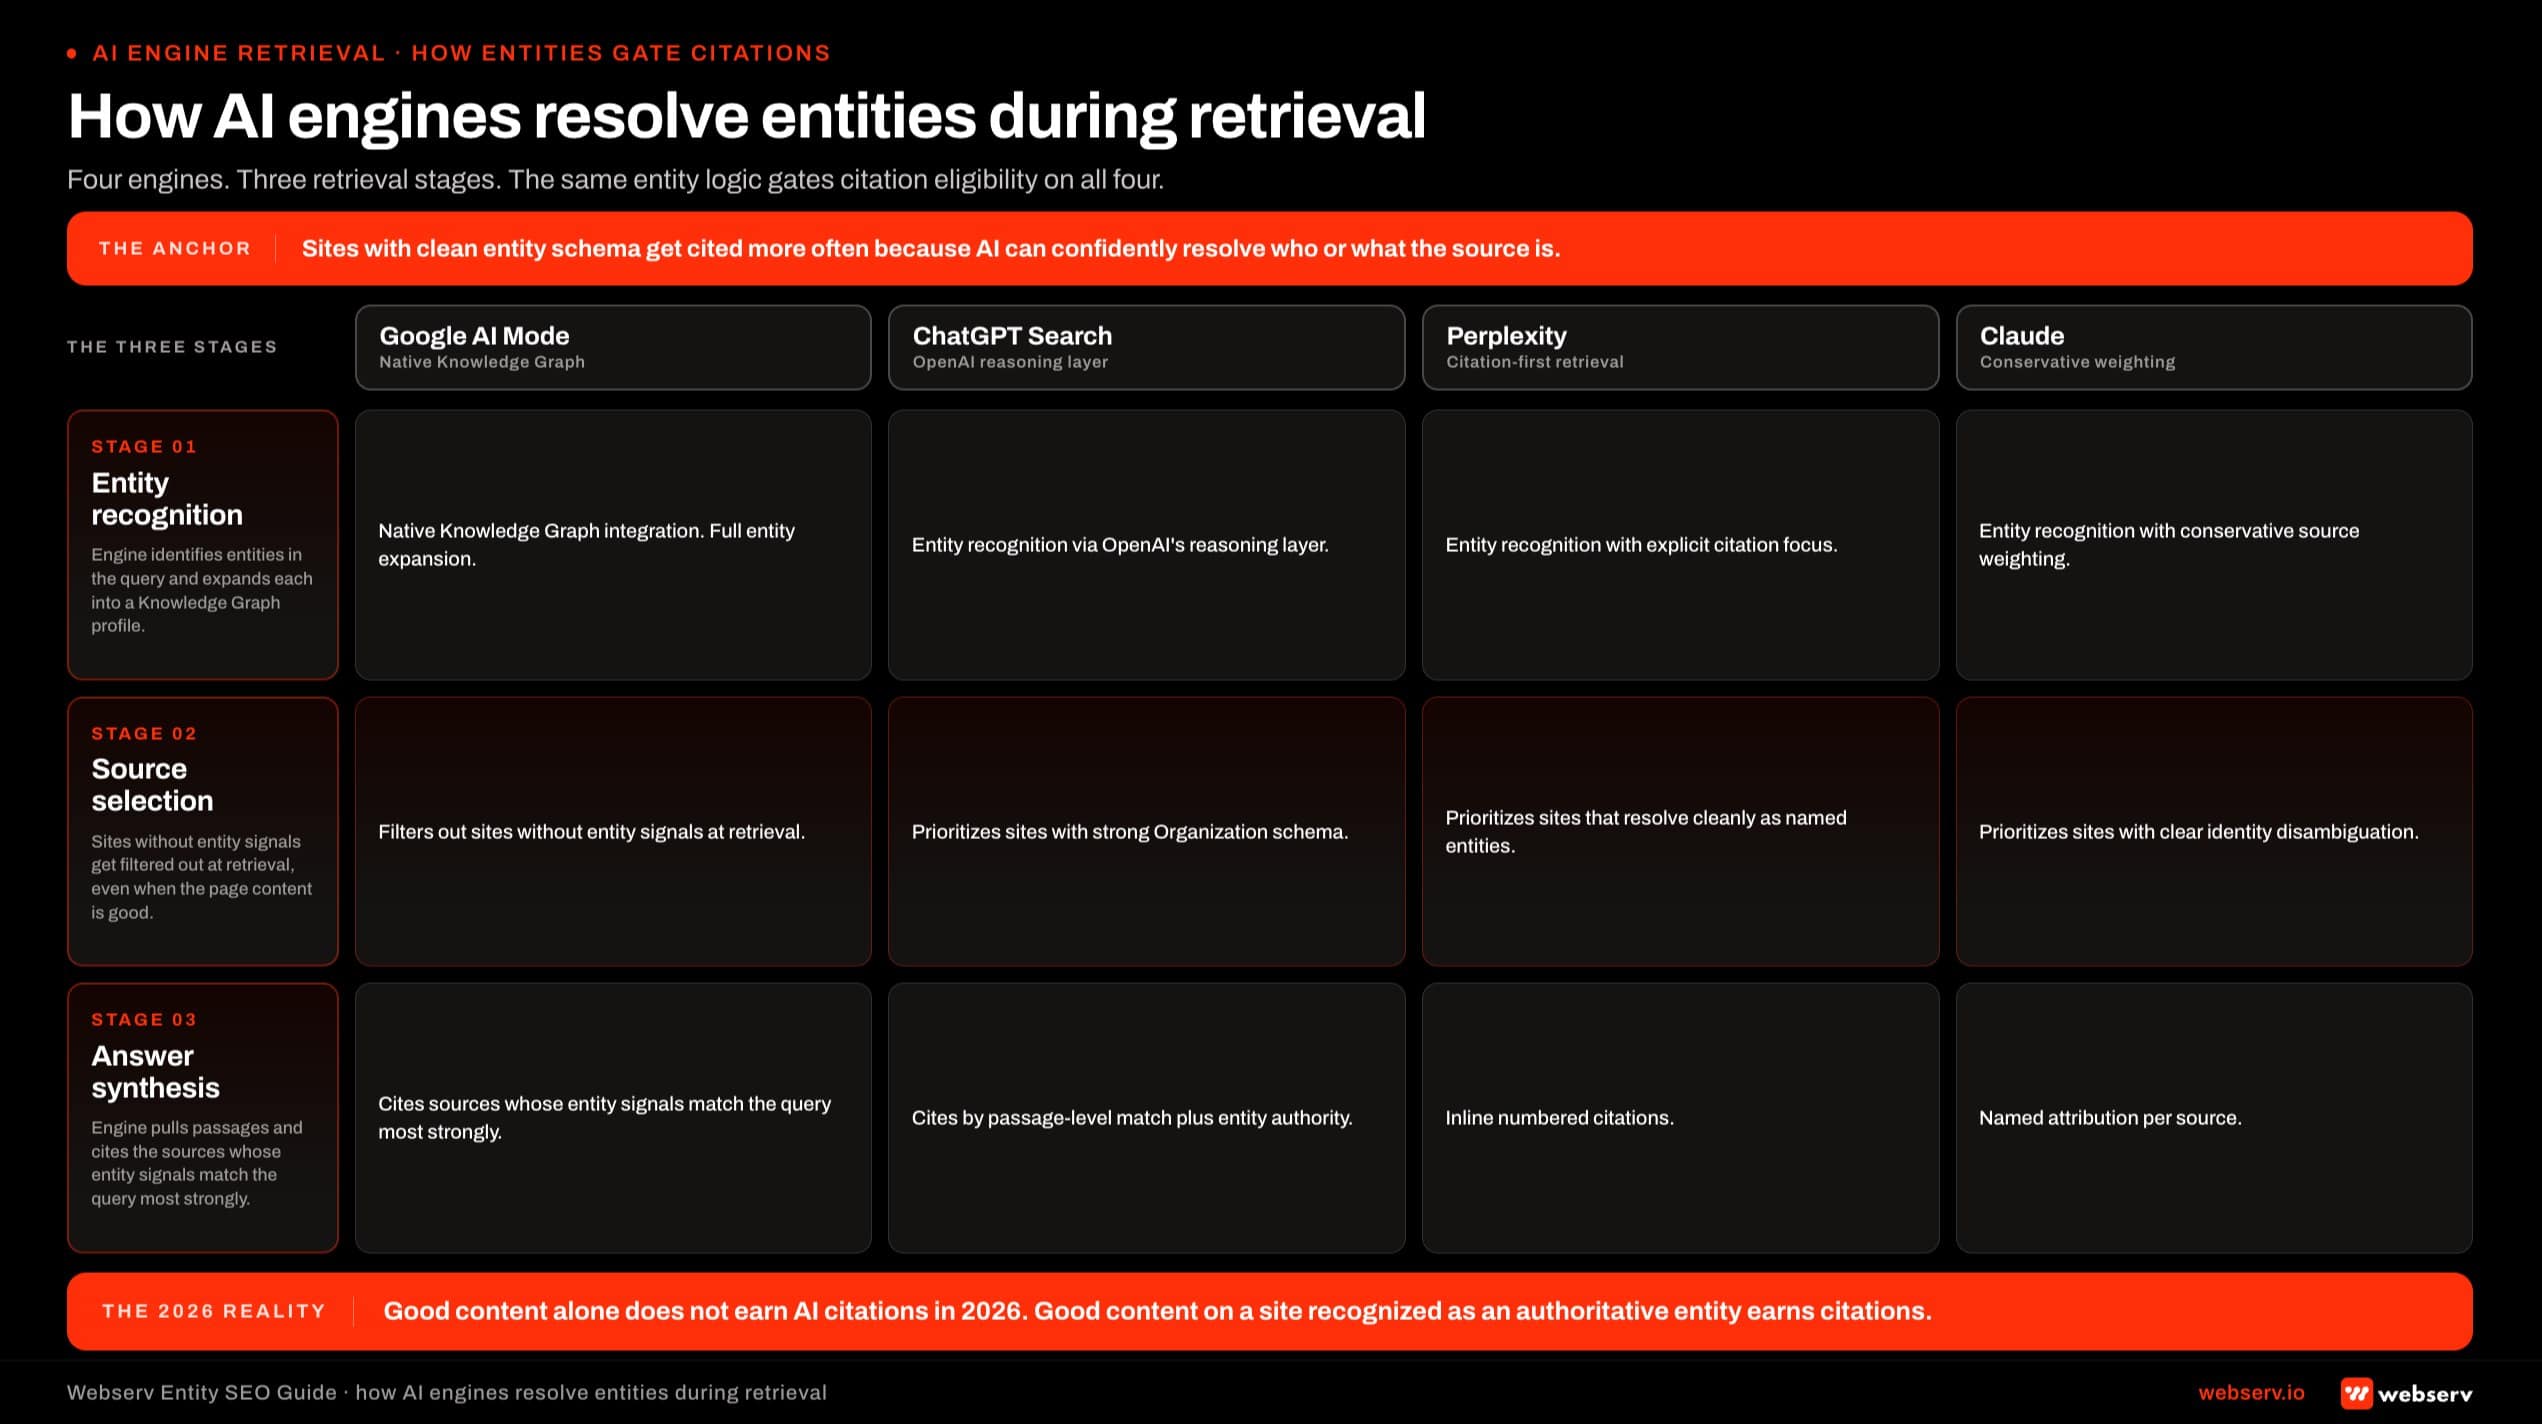 Infographic titled ‘How AI engines resolve entities during retrieval’.
Entity recognition. When the user submits a query, the AI engine identifies the entities in the query (residential treatment, opioid addiction, San Diego, etc.). It then expands each entity into its Knowledge Graph profile: related concepts, synonyms, geographic context, parent and child topics.
Source selection. The engine looks for relevant, trustworthy sources for the topics in the expanded query. Consistent organization details, credentialed authors, and clear disambiguation make a source easier to identify.
Answer synthesis. The engine pulls passages from the selected sources and synthesizes the user-facing answer, citing the sources whose entity signals match the query most strongly. This is the same query fan-out architecture that powers AI Mode, decomposing the user prompt into multiple related sub-queries and finding passages for each.
The practical implication: good content is the foundation for earning AI citations in 2026. Clear entity signals help systems identify who published it.
For treatment centers, this changes what the optimization work looks like. The content team can produce a 3,000-word piece on dual diagnosis care that is clinically rigorous, structurally clean, and AEO-optimized at the passage level.
If the facility publishing the piece has no Organization schema, no knowsAbout declarations for dual diagnosis, no Person schema on the author, and no Knowledge Graph entity record, the facility makes it harder than necessary for AI engines to identify who published the piece.
The entity audit for a treatment center
The starting point is to understand what entity signals your site currently sends and what gaps exist. A 90-minute audit covers most of what matters.
Step 1: Knowledge Panel check. Search your facility name in Google. If a Knowledge Panel appears on the right side of the desktop results, your facility has a basic Knowledge Graph entity record. If no panel appears, the facility is not recognized as a distinct entity, which is the highest-priority gap to close.
Step 2: Schema inventory. Run the homepage and 3 to 5 representative pages through Google’s Rich Results Test. Note which schema types are present. Most BH operator sites I audit have either no schema or generic LocalBusiness schema with no specialization markup.
The target inventory is Organization + LocalBusiness + MedicalClinic + MedicalSpecialty on the homepage, with Article + Person schema on blog content and Service schema on level-of-care pages.
Step 3: sameAs audit. Check whether your Organization schema (if any) declares sameAs properties pointing to LinkedIn, ASAM, Joint Commission accreditation listing, Psychology Today, and your state’s treatment provider registry. These external entity references are how Google’s reasoning engine validates that your organization is the same entity across multiple authoritative sources.
Step 4: Author entity check. Pull 5 random blog posts and check whether each one has Person schema for the author, with credentials, jobTitle, and sameAs links to the author’s professional profiles. Most BH sites I audit have anonymous bylines or first-name-only attribution, both of which fail the 2026 E-E-A-T author entity bar.
Step 5: knowsAbout audit. Pull the Organization schema (if present) and check the knowsAbout array.
Most treatment center sites have either no knowsAbout declarations or generic terms like “addiction treatment” and “rehab.” The target declarations are specific clinical topics the facility genuinely specializes in: dual diagnosis, trauma-informed care, medication-assisted treatment, specific clinical modalities, specific populations served.
The audit produces a prioritized gap list. Most operators have all five gaps to some degree. The remediation order I recommend is Organization + LocalBusiness first (foundational), then sameAs external links (entity disambiguation), then knowsAbout declarations (topical authority), then Person schema on authors (E-E-A-T), then MedicalClinic and MedicalSpecialty (clinical entity recognition).
The five schema types every treatment center needs
The 2026 schema stack for behavioral health follows what some practitioners call the “unbroken chain” pattern. Five interconnected schema types deployed consistently across the site.
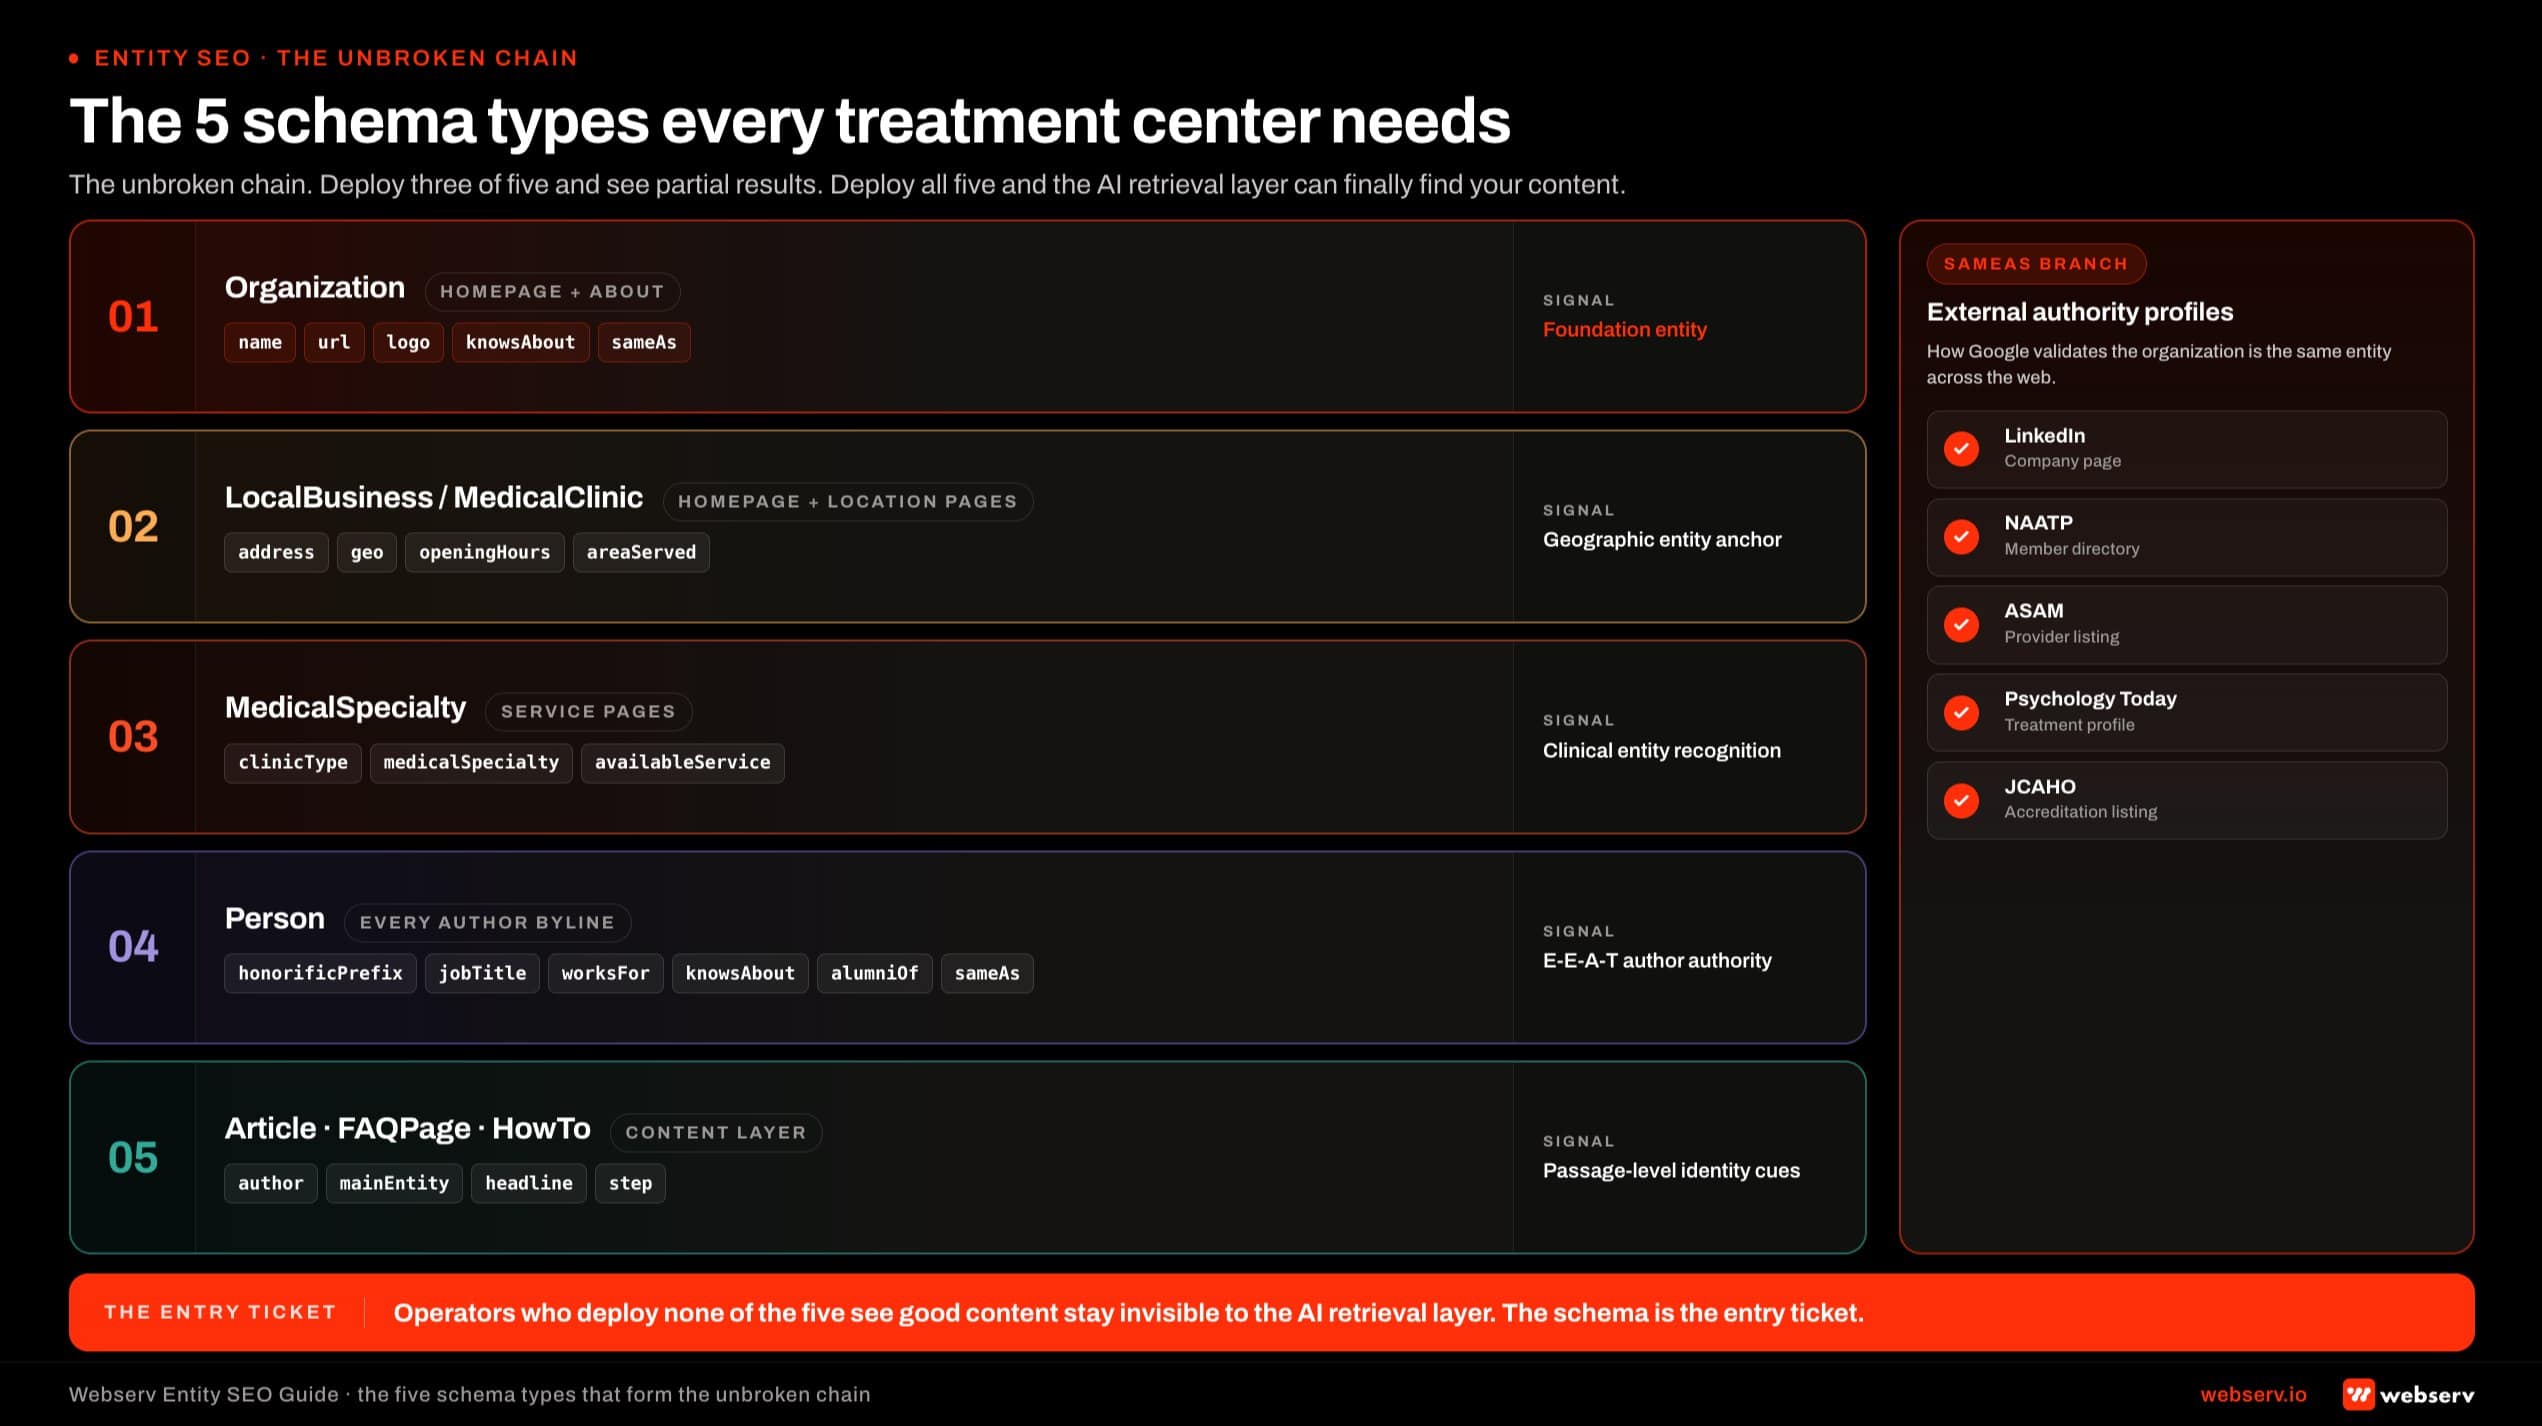 Infographic titled ‘The 5 schema types every treatment center needs’.
Organization schema on the homepage and About page. Declares the facility as an entity. Includes name, URL, logo, founding date, founder, contact info, sameAs properties pointing to LinkedIn and authoritative directories, and the critical knowsAbout property declaring the topical domains where the organization has expertise. Schema.org’s Organization documentation covers the full property set.
LocalBusiness schema (or its specialization MedicalClinic) on the homepage and location pages. Anchors the facility to a specific physical address with geo coordinates, hours of operation, payment methods accepted, and area served. This is the entity signal that connects your facility to geographic queries, and the foundation that the local SEO playbook builds the Google Business Profile and citation layer on top of.
MedicalClinic and MedicalSpecialty schema on service pages. Identifies the clinic type, the medical specialties offered (psychiatry, addiction medicine, dual diagnosis), and the conditions treated. This is what makes the facility discoverable for clinical queries that go beyond simple geography.
Person schema on every author byline. Declares the author as an entity with credentials, jobTitle, knowsAbout topics, alumniOf for education, and sameAs properties pointing to the author’s LinkedIn, professional licensure records, and any other authoritative profiles. This is the E-E-A-T author signal Google’s quality systems weigh on YMYL content.
Article schema on the content layer, with author Person references. FAQPage and HowTo markup are optional now: Google retired HowTo rich results in 2023 and FAQ rich results in May 2026. Per Google Search Central’s structured data documentation, Google uses structured data to understand the content of a page. The same logic our healthcare blog and article writing standards build around.
The five types interconnect through entity references. The Article’s author Person references back to the Organization. The Organization references the LocalBusiness/MedicalClinic. The MedicalSpecialty references the Organization. The result is an unbroken chain of entity relationships that the AI reasoning engines can traverse to validate authority and assess source credibility.
Deploying the full chain gives search systems the most complete, consistent picture of the facility. Skipping layers leaves gaps they have to fill from other sources.
“Good content alone does not earn AI citations in 2026. Good content on a site that is recognized as an authoritative entity earns citations.”
Preston Powell, Chief Executive Officer, Webserv
knowsAbout: the 2026 lever most operators miss
Among the five schema types, the knowsAbout property on Organization and Person schema is the single most underweighted lever in 2026. Google does not rank pages on any single schema property, but knowsAbout is one of the clearest ways to state, in machine-readable form, what topics your organization and your clinicians cover.
The property declares the topics your organization or your authors have expertise in. AI Mode uses these declarations when selecting sources for specific query categories.
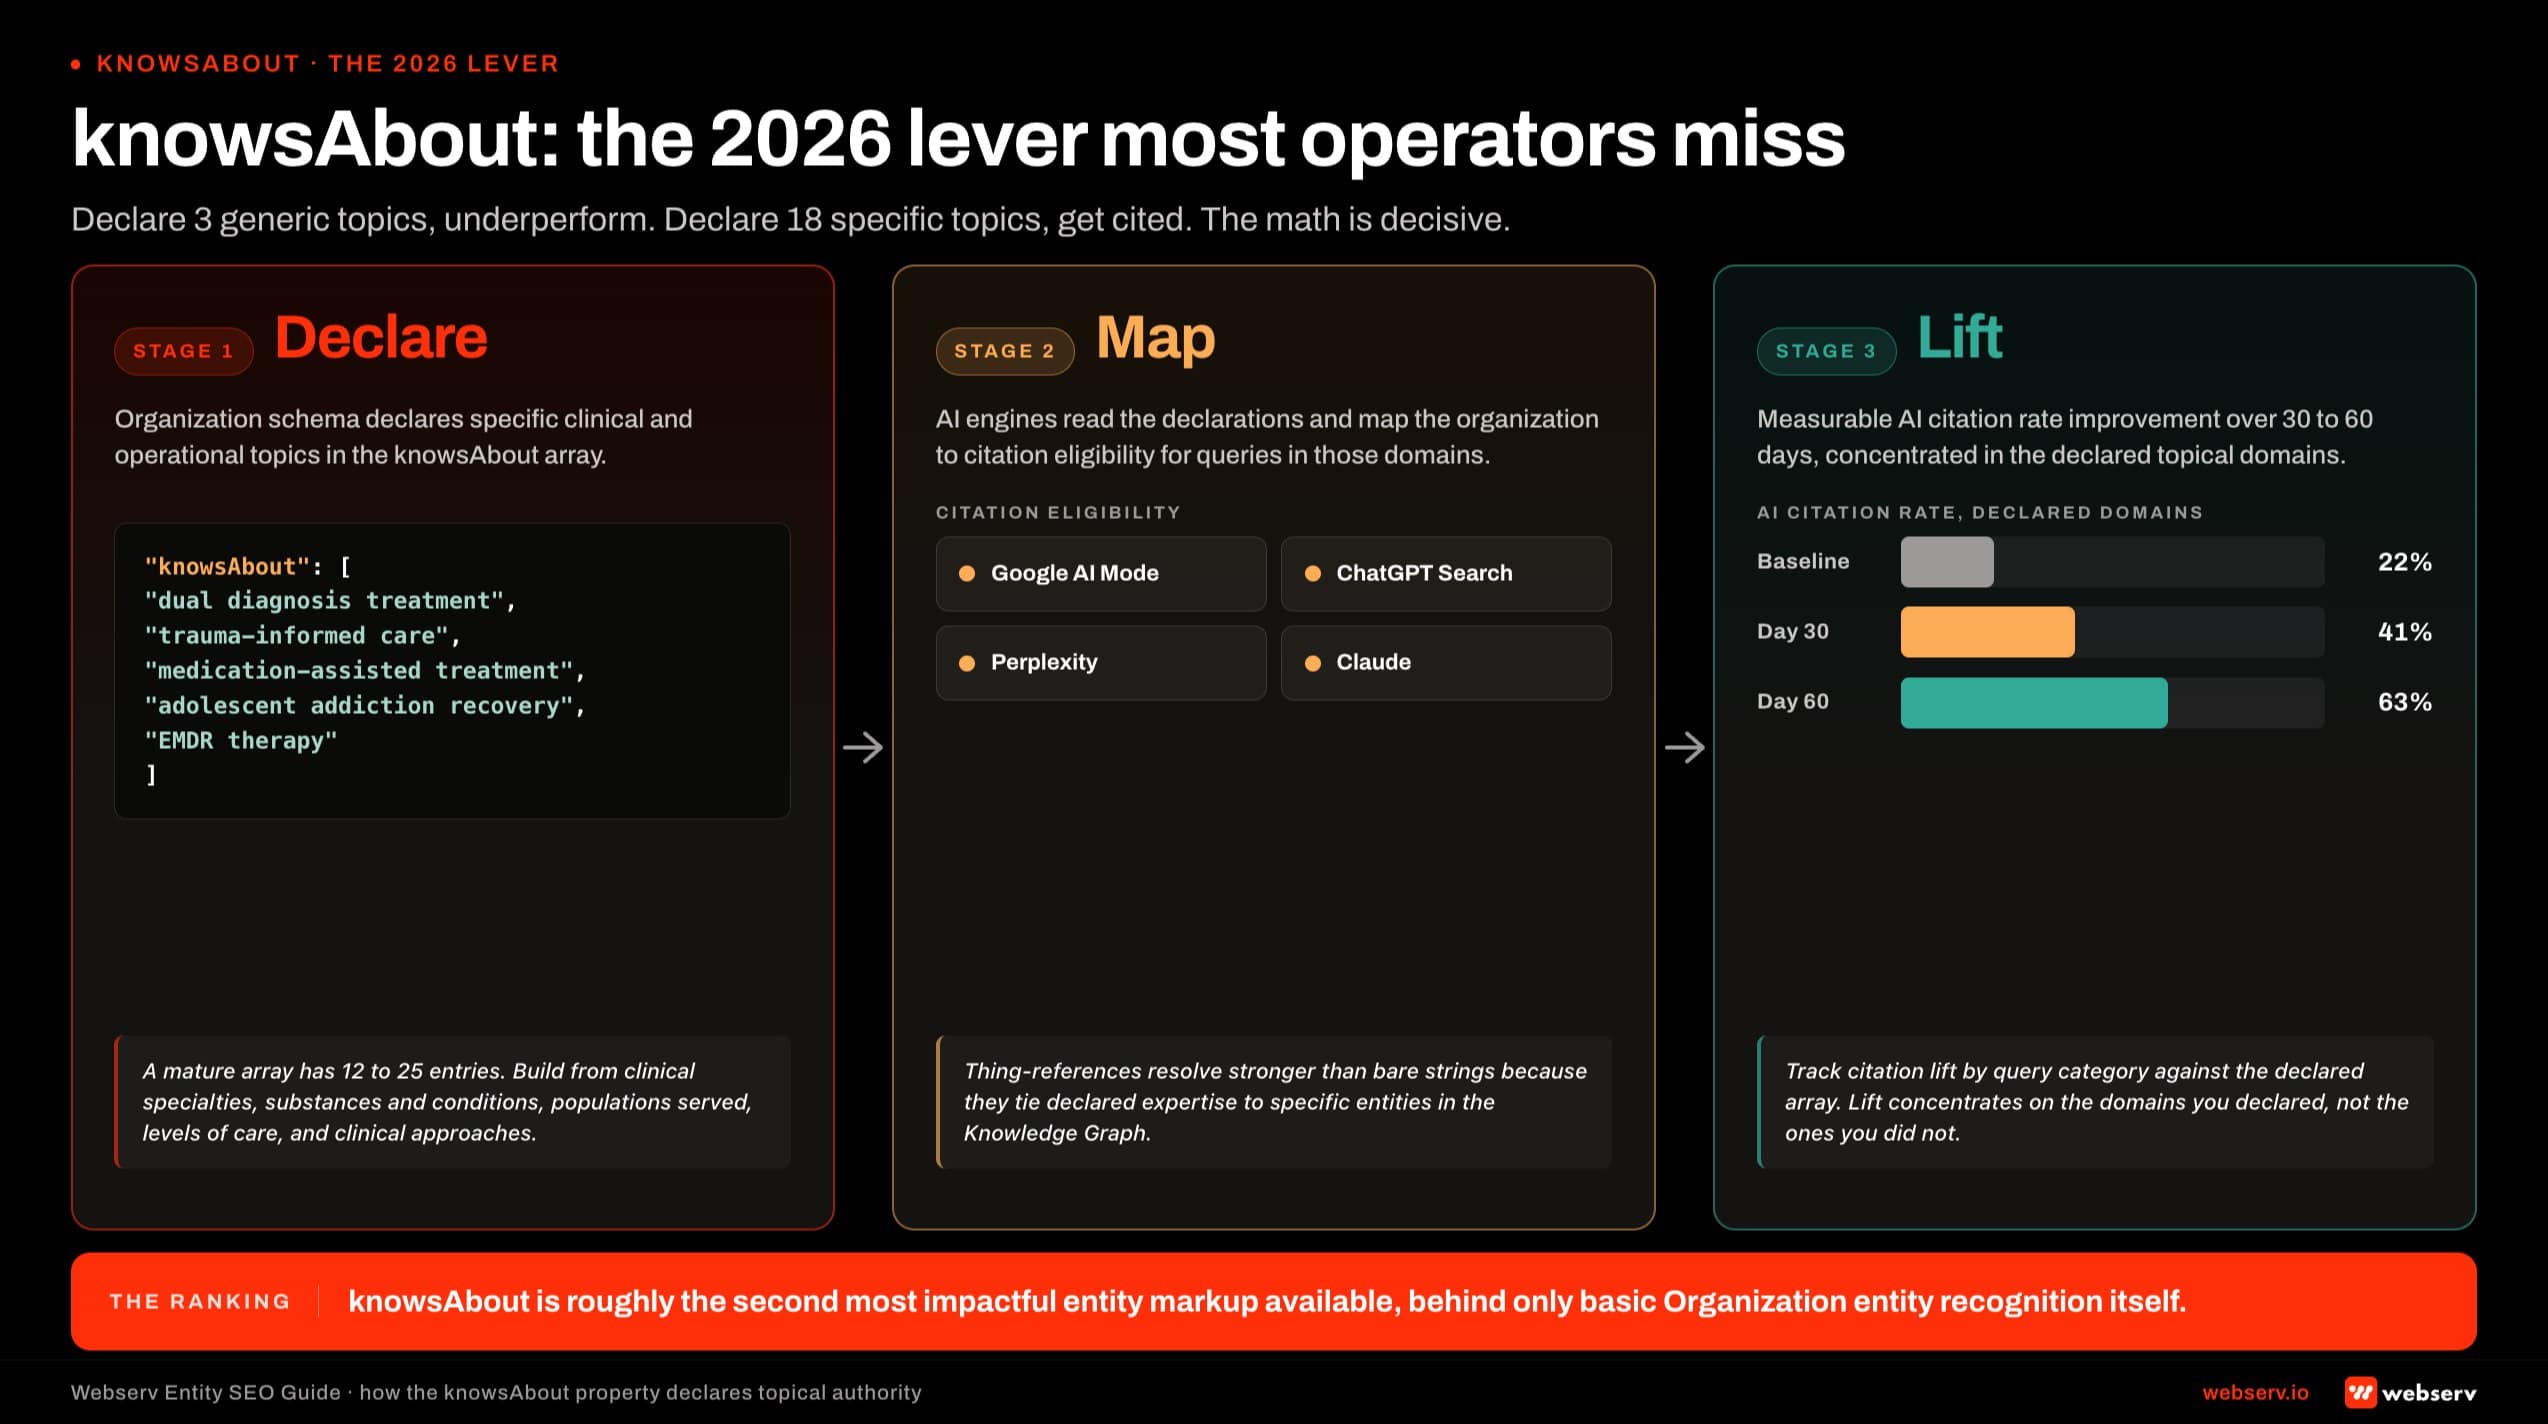 Infographic titled ‘knowsAbout: the 2026 lever most operators miss’.
An organization with knowsAbout declarations for “dual diagnosis treatment,” “trauma-informed care,” “medication-assisted treatment,” and “adolescent addiction recovery” states its expertise more precisely than one with no declarations or generic ones like “addiction treatment.”
The implementation is simple to describe and easy to do badly. The Organization schema’s knowsAbout property accepts an array of either string values (“dual diagnosis treatment”) or Thing references to specific concept entities. The string approach works for general visibility. The Thing-reference approach is stronger because it ties your declared expertise to specific entities in the broader Knowledge Graph.
A reasonable starting knowsAbout array for a residential treatment center looks like:
- Specific clinical specialties (dual diagnosis, trauma treatment, medication-assisted treatment, EMDR)
- Specific substances and conditions treated (alcohol use disorder, opioid use disorder, polysubstance, methamphetamine)
- Specific populations served (adults, adolescents, women, veterans, professionals, LGBTQ+ specific)
- Specific levels of care offered (residential, PHP, IOP, MAT, detox, outpatient)
- Specific clinical approaches (CBT, DBT, family therapy, group therapy, somatic experiencing)
Declare the specific topics your content and clinicians actually cover, and skip generic ones. Declarations without supporting content don’t add credibility.
How SoCal Sunrise generated 85 admissions and 2,297% ROI from SEO in 6 months
A ground-up SEO rebuild using the Pathfinder Parents Methodology turned an invisible online presence into a top-ranking admissions engine.
Read the case study →85 admits and 3,152 leads attributed to organic
Author entity and the E-E-A-T entity signal
Author identity is table stakes for YMYL healthcare content: Google’s rater guidelines ask who created the content and whether they have the expertise. A blog post with an anonymous byline or a first-name-only attribution struggles in YMYL rankings, while a blog post with a credentialed Person entity behind it accumulates author-level authority that compounds across the cluster.
The Person schema for a clinical author should declare:
- Full name and
honorificPrefix(LCSW, LMFT, MD, PhD) jobTitleand role at the organizationworksForreference back to the Organization entityknowsAbouttopics specific to the author’s clinical expertisealumniOffor medical school, graduate school, professional training programssameAslinks to LinkedIn, state licensure records, Psychology Today profile, professional society listings (ASAM, APA, AMA)
The deployment pattern is to embed the Person schema on the author byline of every piece they have written, with consistent entity identity across pieces. An author who has written 30 posts with consistent Person schema is a stronger entity signal than the same author with inconsistent or missing schema across pieces.
For treatment centers running the clinical-reviewer model where a senior clinician reviews content drafted by non-clinical writers, the Person schema attaches to the reviewer. The byline can include both names (writer and reviewer), but the entity authority signal lives with the credentialed reviewer.
The compounding effect is what makes this matter. Sites that build a small library of consistent author entities (3 to 6 credentialed clinicians, each with Person schema and a sustained byline history) develop topical authority faster than sites with rotating anonymous content. The author entity is the bridge between content quality and organizational authority, and Google’s quality rater guidelines treat who created the content as a core question for health topics.
How entity SEO compounds with the rest of the AEO program
Entity SEO is not a standalone discipline. It is the substrate that makes the rest of the AEO work productive. Three adjacent layers compound with the entity work.
Passage-level content optimization. The fan-out query architecture rewards content with atomic answer paragraphs, semantic triples, and clean H2/H3 structure. Entity SEO determines whether your site is in the candidate set for retrieval at all. Passage optimization determines whether your passages get selected once the site is in the candidate set. Both layers matter. Neither works alone.
Topical cluster depth. Entity declarations only land if the surrounding content supports them. An Organization declaring knowsAbout for “trauma-informed care” with no content cluster on trauma-informed care reads as an unsubstantiated claim and gets discounted. The content cluster work that builds out depth on each declared topic is what gives the entity signals credibility. Entity SEO and cluster architecture are two sides of the same authority-building process.
Technical SEO foundation. Schema deployment requires a clean technical SEO foundation underneath. Schema that does not validate, schema that conflicts between page types, schema that is missing on key pages — the same pattern that doorway page clusters create at the content layer, where unresolvable signals get the entire site discounted. All of these undermine the entity signal. New facilities have it easier here: the foundational site work a new treatment center ships first builds this base before the content layer exists.
Sites with strong schema architecture on a clean technical base see the full lift from entity work. Sites with schema layered onto a broken technical foundation see degraded results, especially on sites still working through mobile-first indexing issues that affect how schema renders to crawlers.
The synthesis is that entity SEO is a foundational AEO investment for a treatment center, but only if the content, cluster, and technical layers are healthy enough to support it. Deployed as a standalone fix on a thin content site, it does little. Deployed on top of an already-mature content and technical program, it helps the rest of the work get recognized. For operators considering external help, the AI optimization agency selection question maps directly to this stack maturity assessment, and the broader behavioral health marketing program compounds when entity work runs alongside the rest.
This ties directly into getting cited in AI search answers, both part of how treatment centers earn visibility in AI-generated answers.
entitymap.json: Declaring Your Entities to AI Crawlers
What entitymap.json Is
entitymap.json is a proposed open standard published by Fred Laurent (Waikay) and Dixon Jones (InLinks) at entitymap.org, released as v1.0 on April 7, 2026, under a CC BY 4.0 license. The specification lives on GitHub and defines a JSON schema for publishing a machine-readable index of the entities, relationships, and evidence a site covers.
The premise is that AI retrieval systems today operate at the page level. They fetch HTML and extract passages without a structured awareness of the underlying entities, publisher identity, or the relationships between concepts on the site. This produces three specific failures.
Disambiguation. The same concept under different surface forms gets treated as separate signals rather than as one entity. On a treatment center site, “PHP,” “Partial Hospitalization,” and “day treatment” refer to the same clinical program. AI retrieval that reads only the page HTML often does not resolve them cleanly to one entity.
Attribution. When a passage of content gets retrieved into an AI answer, the publisher identity often does not survive the aggregation. Treatment center content that gets consumed into an AI Overview loses the citation trail. That trail would otherwise tell the AI system (or a downstream user) that the content was originally published by a specific accredited operator at a specific URL.
Relationships. Connections between concepts (which clinician works at which facility, which modality is offered in which program, which condition is treated at which LOC) are buried in prose rather than declared as explicit, typed relations.
entitymap.json addresses those three failures by giving publishers a standard way to declare their entities, evidence, and relationships in a machine-readable file at a predictable URL.
What It Looks Like
An entitymap consists of two files published at predictable root-level URLs on your domain. The machine-readable JSON file lives at yoursite.com/entitymap.json. A companion human-readable HTML view lives at yoursite.com/entitymap.html.
The JSON file contains three core building blocks.
Entities are the named things your organization covers. These include your parent org, your facilities, your programs, your clinicians, your accreditations, and your service areas.
Relations map how those entities connect. Which clinician works at which facility, which modality is offered in which program, which LOC is available at which location.
Evidence chunks are passages from your website that support each entity, linked to their source URL with attribution metadata (publisher name, page title, retrieval timestamp).
A minimal entity entry carries an internal entity ID, a type declaration, a name, and a short description. It also carries a sameAs URL that grounds the entity in an external authority (Wikidata, LinkedIn, an accreditation body’s directory), plus one or more evidence chunks.
The specification defines 23 standard relationship predicates in v1.0. These are the verbs that connect entities.
For treatment centers, the predicates that matter most are OFFERS (facility offers program), TREATS (program treats condition), EMPLOYS (facility employs clinician), ACCREDITED_BY (facility accredited by JCAHO or CARF), LOCATED_IN (facility located in service area), and PART_OF (facility part of parent organization).
entitymap.json v1.0 at a glance
Apr 7, 2026
v1.0 release date under CC BY 4.0 license
23
Standard relationship predicates defined in the v1.0 spec
4 surfaces
v5.7 AI-readability stack: Schema.org, llms.txt, entitymap.json, AI Info page
20-40 hrs
Entity inventory for a single-facility mature site
How to Build One for a Treatment Center
The load-bearing work happens before you touch the JSON file. It is the entity inventory.
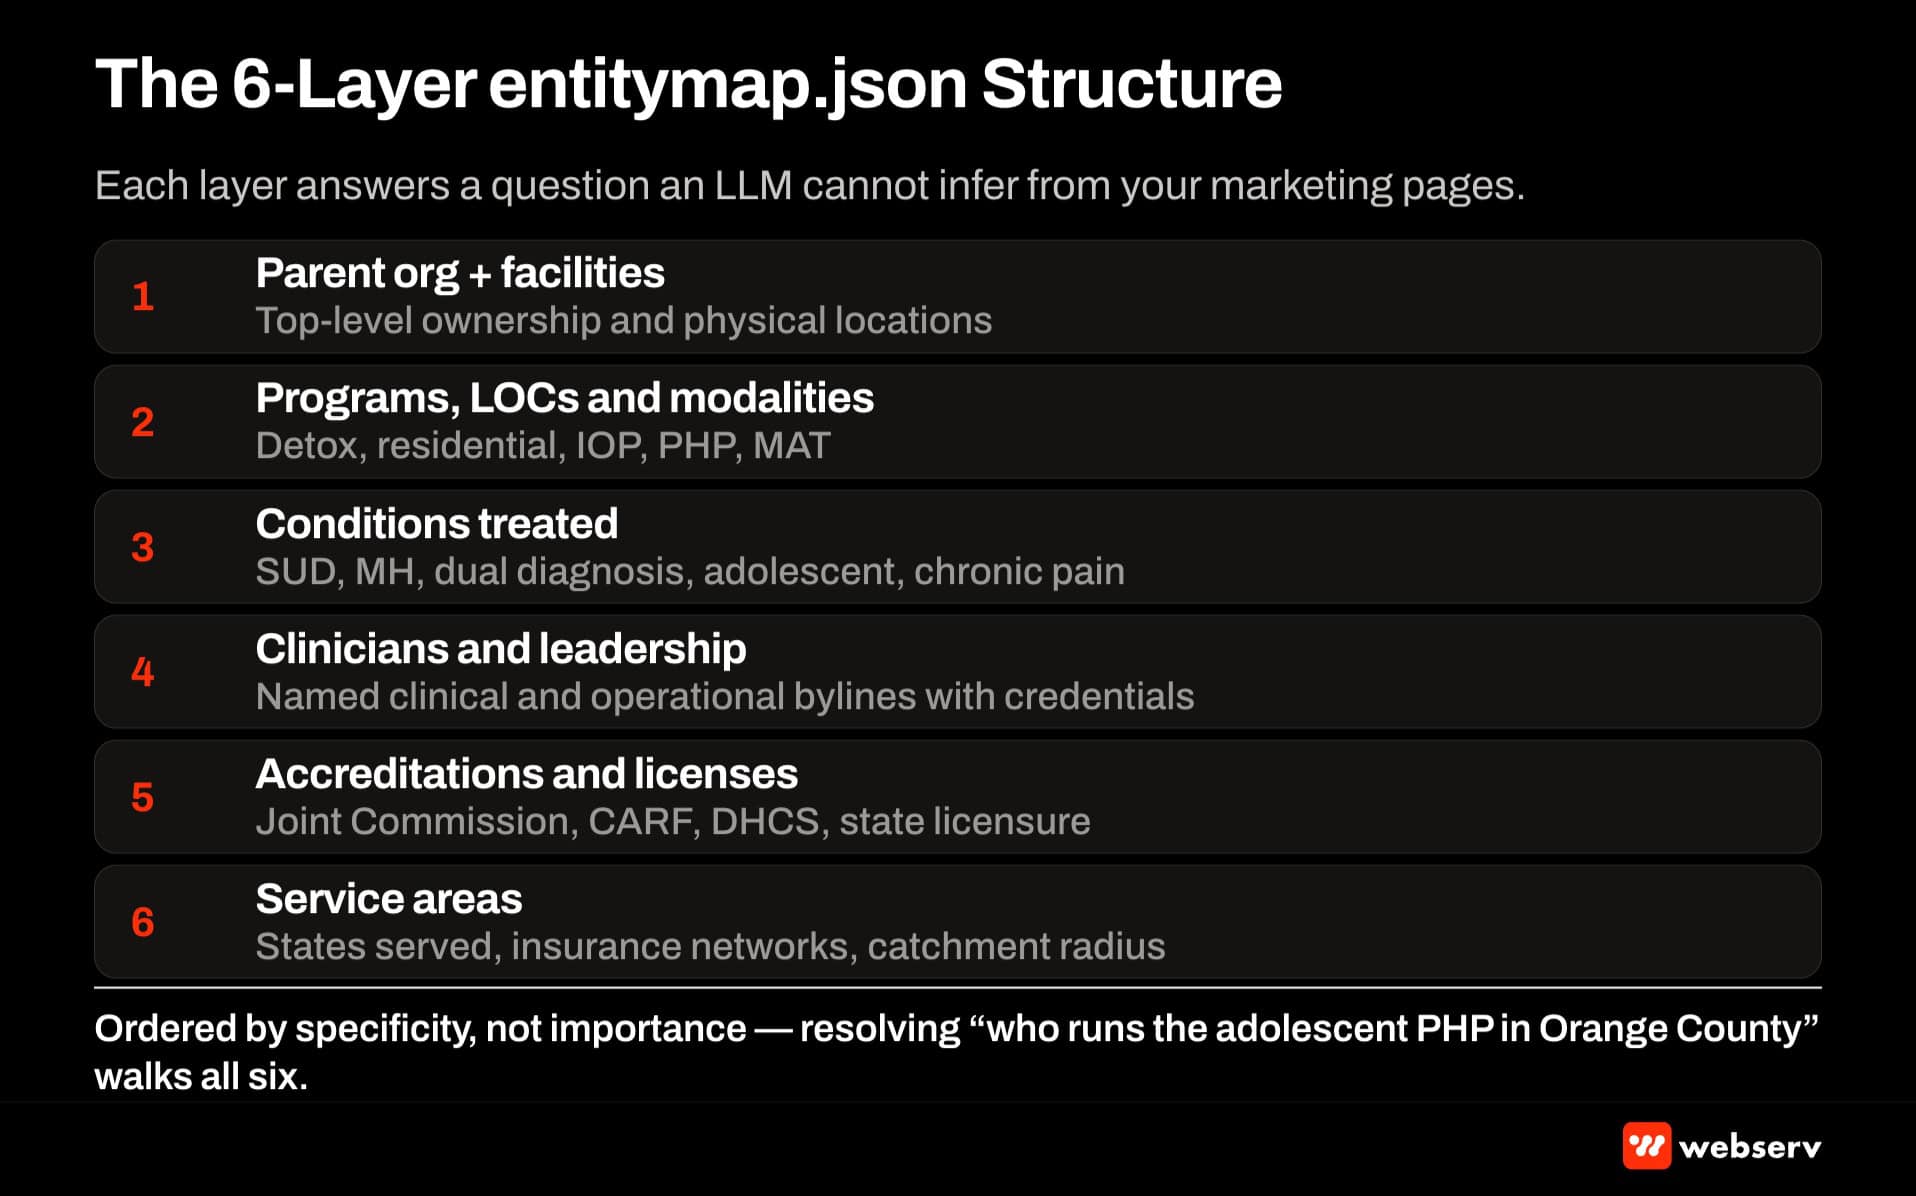
Layer one: the parent org and facilities
The parent organization is entity zero. Each physical facility is a distinct entity with a canonical name, physical address, phone number, NPI number, state license number, and sameAs links to Google Business Profile, the state licensing database entry, and any relevant accreditation directory.
Layer two: programs, LOCs, and modalities
Each program (residential, PHP, IOP, outpatient, detox) is a distinct entity, offered by a specific facility via an OFFERS relation. Each modality (individual therapy, group therapy, family therapy, TMS, ketamine-assisted therapy, MAT) is a distinct entity offered by a program via an OFFERS relation.
Layer three: conditions treated
Each primary condition or diagnosis the facility treats (SUD, AUD, dual diagnosis, PTSD, depression, anxiety, bipolar, OCD, eating disorders) is a distinct entity, with TREATS relations declared from the program entity to the condition entity.
Layer four: clinicians and leadership
Each clinical author, medical director, program director, and executive is a distinct Person entity, with sameAs links to LinkedIn, state license lookup (state medical board or DPH directory), and any specialty board certification. Our clinical author bio E-E-A-T pass covers the Person entity fields in depth.
Layer five: accreditations and licenses
Each accreditation (JCAHO, CARF), certification (LegitScript), and state license is a distinct entity, with ACCREDITED_BY relations from the facility entity to the accreditation entity. Each accreditation entity carries a sameAs URL to the accreditation body’s directory listing for that specific facility, which is the load-bearing external signal for the AI system.
Layer six: service areas
Each geographic service area (city, county, MSA) is a distinct Place entity, with SERVES relations from the facility entity to the service area entity. This layer only makes sense for facilities with a meaningful geographic service footprint.
Once the six layers are inventoried, the JSON generation itself is mechanical. The Waikay reference generator handles the conversion. The validator at entitymap.org/validate confirms conformance to v1.0.
Evidence Chunks: The Payload That Matters Most
The predicate graph gets attention, but the evidence chunks are the piece that AI retrieval systems could actually use directly. Each entity in the map should carry one or more evidence chunks: passages from your site content, linked to their source URL, that support the entity.
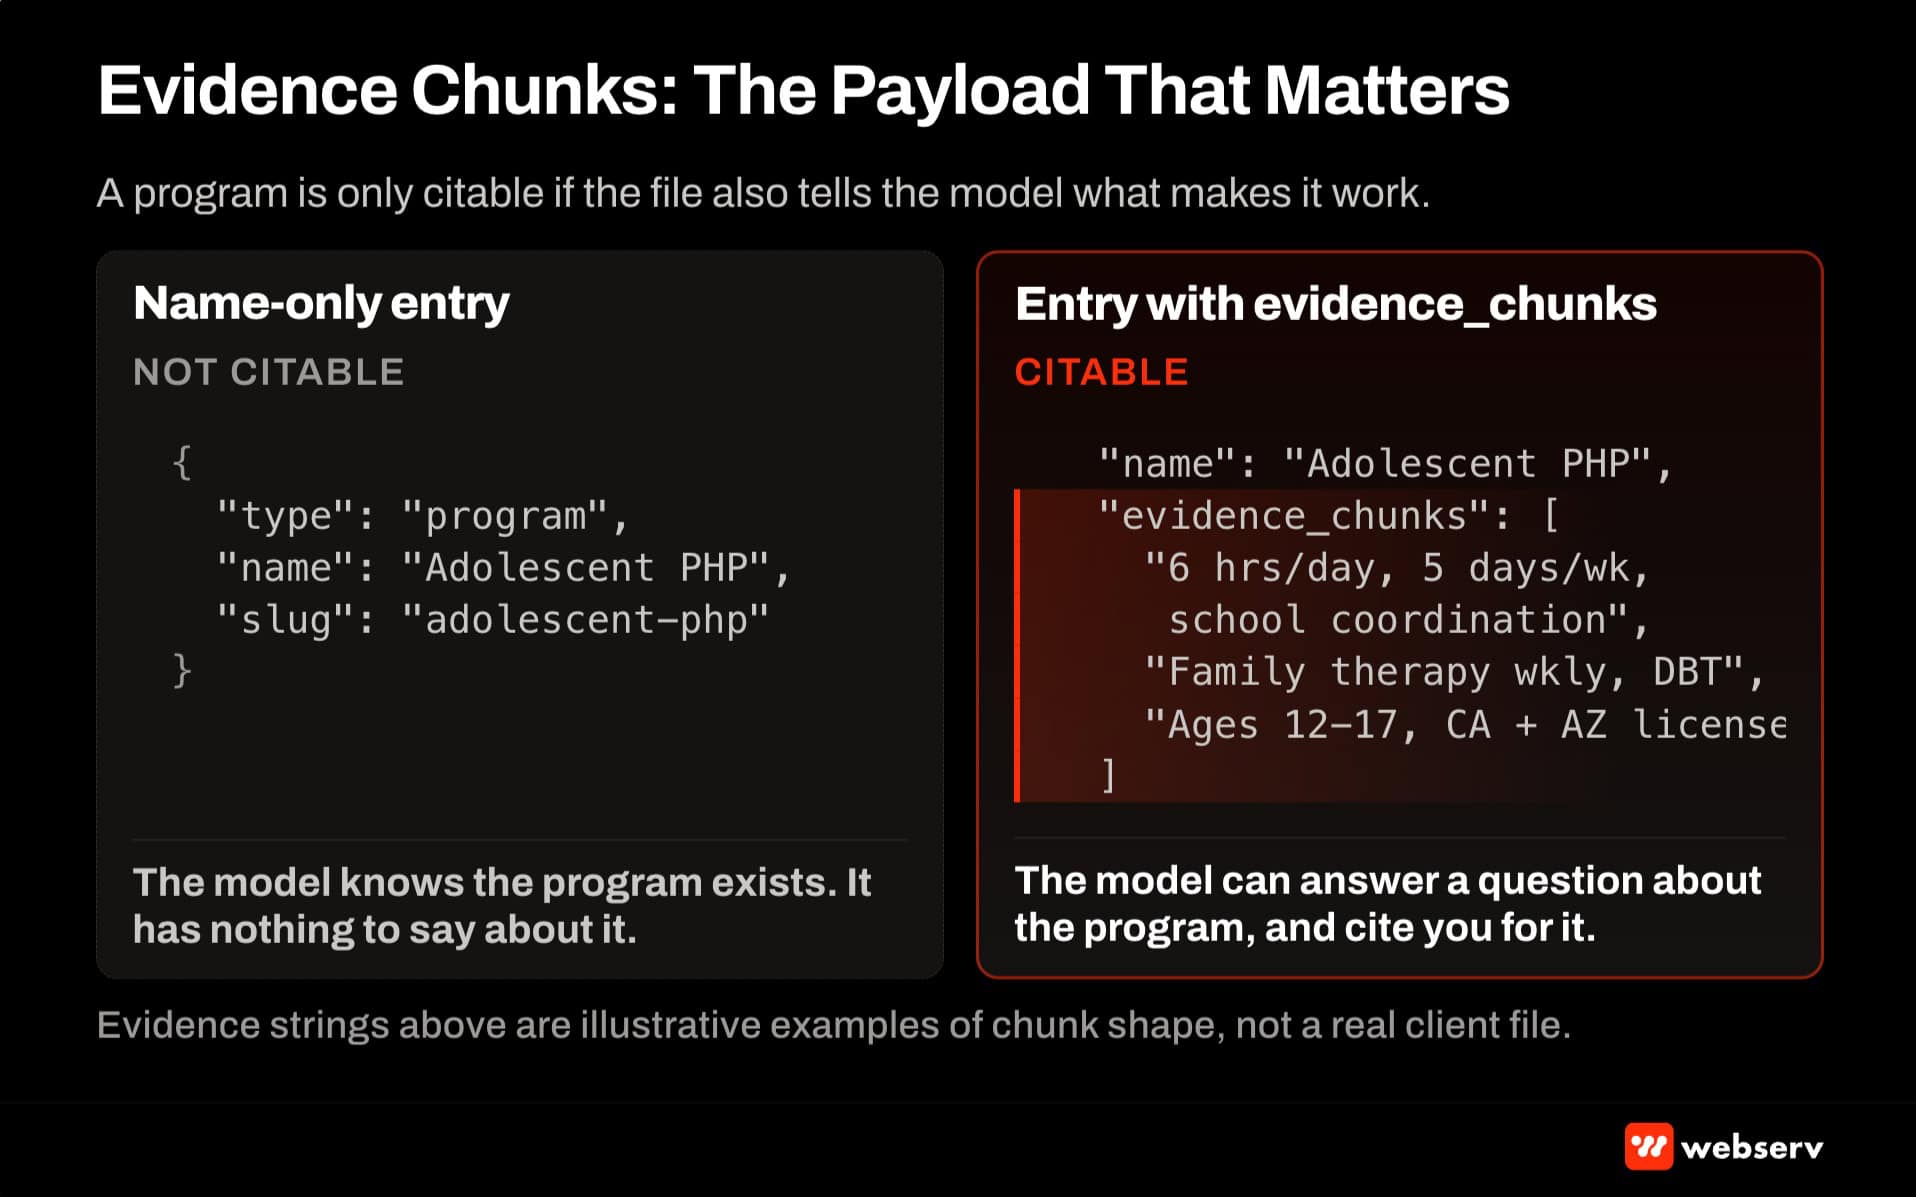
For a treatment center, the evidence chunks are the passages on your site that describe each entity in your own words with your own operator perspective. The description of your specific TMS protocol from your TMS service page. The description of your specific dual-diagnosis approach from your dual-diagnosis LOC page. The bio-graph passage that describes your medical director’s specific credentials from your team page. Each chunk carries a sourceUrl that anchors it to the source page and metadata that identifies you as the publisher.
Evidence chunks are the mechanism that closes the attribution gap. When a RAG pipeline reads your entitymap, it does not have to guess where the evidence came from. The chunk carries the URL, the page title, the publisher name (your organization), and the retrieval timestamp. If the pipeline uses those chunks to generate an AI answer, the attribution trail survives.
This is also the reason the entitymap pre-work is valuable regardless of AI adoption. Producing the evidence chunks forces you to write and maintain the specific passages that describe each entity in a way that would hold up under retrieval. That discipline is the same one behind the E-E-A-T standard for clinical content and the get-cited-in-AI-search framework our practice deploys.
Publishing and Declaring the Map
The publishing step is straightforward. Upload entitymap.json and entitymap.html to the root of your domain. On WordPress, that means uploading them into the site root at the same level as robots.txt and sitemap.xml, not into /wp-content/uploads/.
The declaration step has three pieces per the v1.0 specification.
The first is a line in robots.txt declaring the file location. The specification uses the syntax EntityMap: https://yourdomain.com/entitymap.json, added as a new line alongside your existing sitemap declarations.
The second is a <link> tag in the site <head>, with rel="entitymap" and type="application/json" and href pointing to the JSON file. This is analogous to the way sitemap.xml gets declared via the <link rel="sitemap"> pattern.
The third is a sitewide footer link to the human-readable entitymap.html companion. The specification calls the footer the most reliable discovery mechanism because it survives changes to robots.txt and head-tag parsing quirks.
What Not to Expect
Two expectations get set incorrectly around entitymap.json.
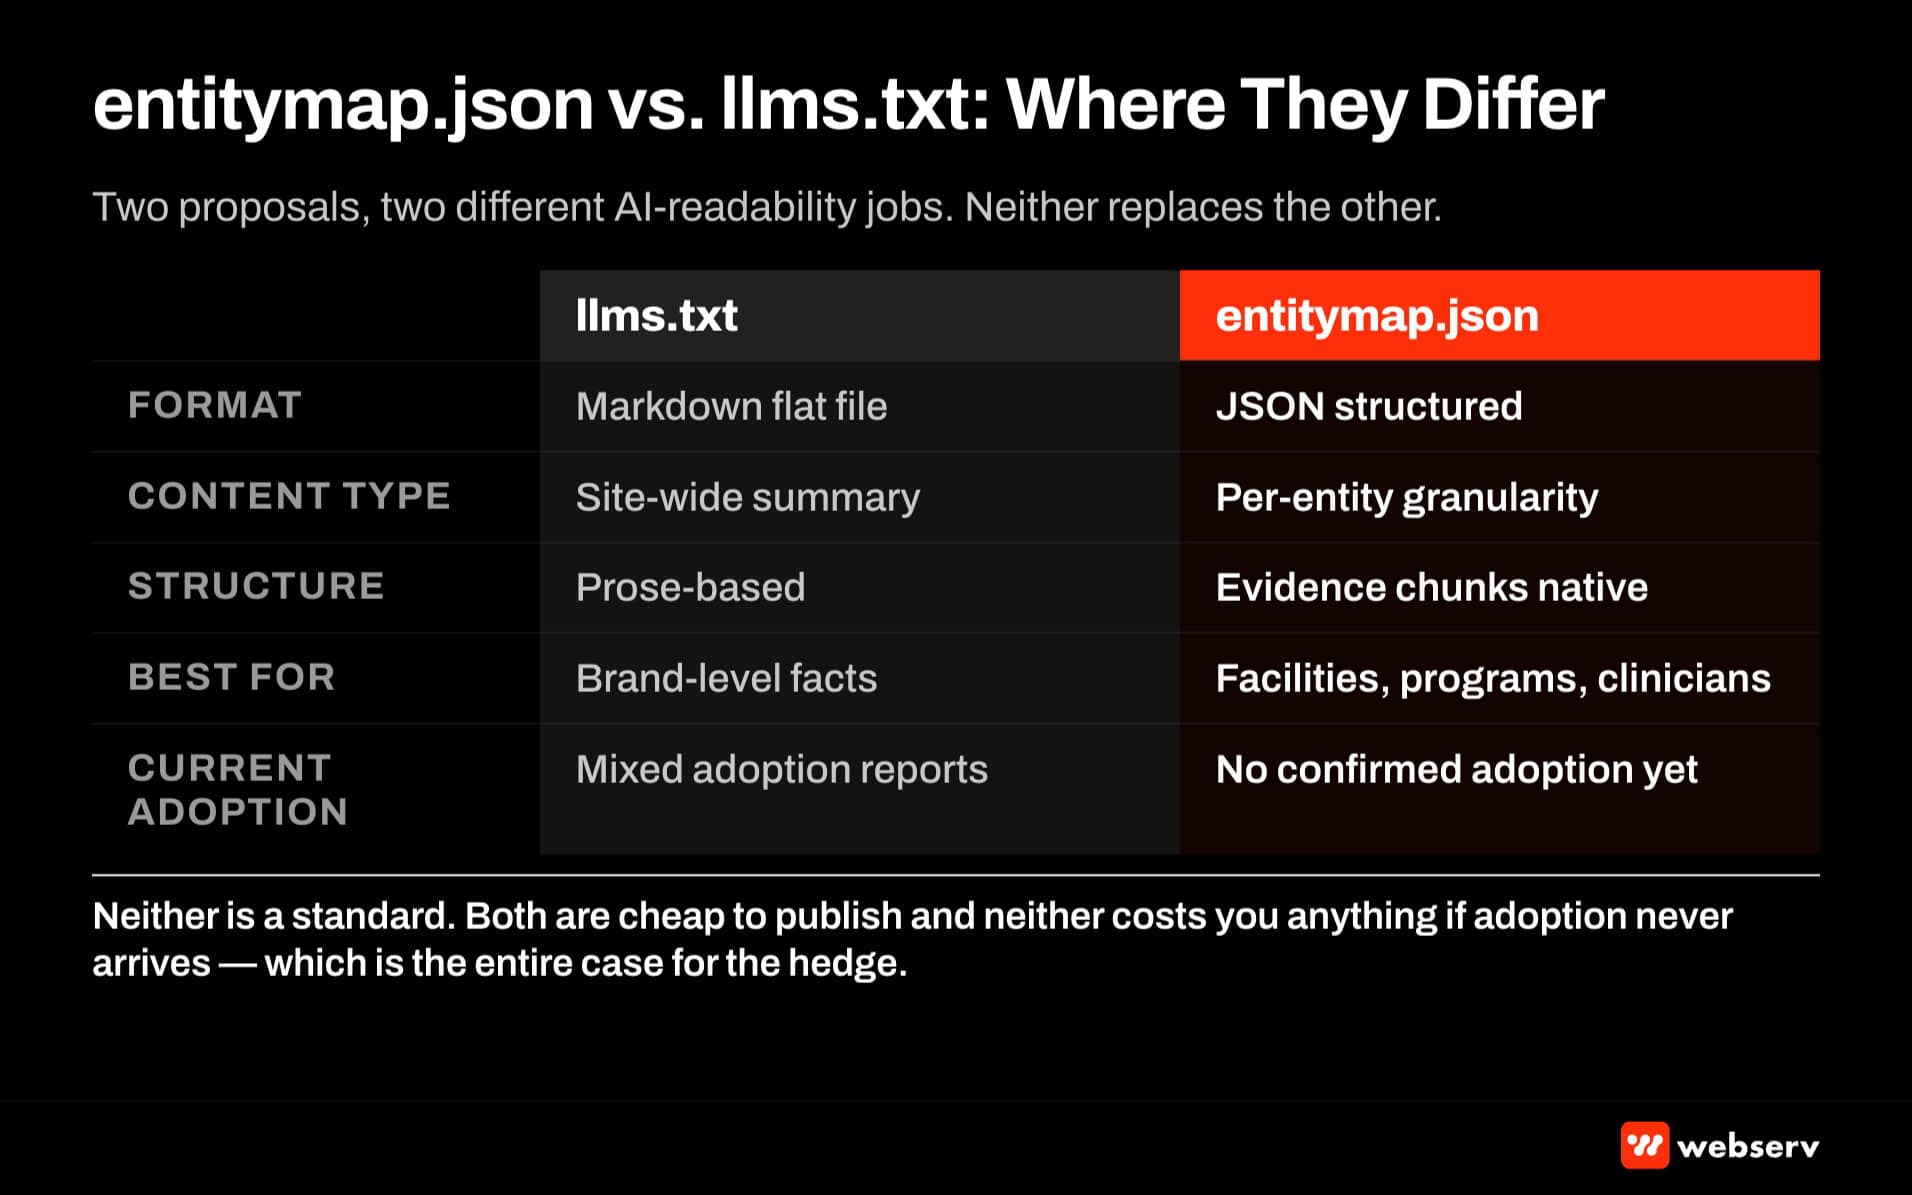
The first is that shipping entitymap.json will produce a measurable rank or citation lift on its own. It will not, at least not attributable to entitymap.json itself. No major AI lab has confirmed consuming the file. The citation lift the Waikay case study reports comes from a compound intervention (entitymap + Schema.org + evidence chunks). That compound intervention would produce similar lift with or without the entitymap file. The correct frame is that entitymap.json is a low-cost hedge, not a rank lever.
The second is that entitymap.json replaces the AI Information page or the Schema.org markup. It does not. The four surfaces are complementary. Building entitymap.json without also deploying Organization + MedicalClinic + Person schema leaves the highest-ROI surface untouched. The pre-work of inventorying entities produces value on all four surfaces at once, which is why treating them as a unified stack rather than four independent projects is the right operating frame.
The correct adoption timeline for entitymap.json matches what llms.txt got in late 2024. Ship it, publish it, forget it. If an AI lab announces consumption, the file is already in place. If none ever does, the pre-work still produced the entity inventory that improved the other three surfaces.
Frequently Asked Questions
How is entity SEO different from traditional SEO?
Traditional SEO optimizes for keyword matching: produce pages that target specific queries, with the queries reflected in the title, headings, and body content. Entity SEO optimizes for entity recognition: establish the organization, its services, its locations, its clinicians, and its topical expertise as recognized entities in Knowledge Graphs that AI reasoning engines use during retrieval.
The two are not opposed. Entity SEO does not replace keyword targeting. It sits above it. A well-targeted page is easier for search systems to trust when the organization behind it is clearly identified.
The practical shift is that the unit of optimization is no longer just the page. It is the page plus the entity (organization, author, service, location) the page belongs to. Optimizing at both levels gives search systems a relevant page and an identifiable source.
What is the Knowledge Graph and why does it matter for treatment centers?
The Knowledge Graph is Google’s database of entities (people, places, things, concepts) and the relationships between them. It launched in 2012 and powers Knowledge Panels and informs how Google understands entities across Search.
For treatment centers, the Knowledge Graph matters because AI reasoning engines use it to resolve “who is this source” during answer synthesis. A facility with a Knowledge Graph entity record (the kind that produces a Knowledge Panel when you search the facility name) is easier for Google’s systems to identify. A facility with no record is harder to disambiguate from similarly named organizations.
Getting into the Knowledge Graph requires entity disambiguation through schema, consistent NAP (name, address, phone) signals across the web, citations from authoritative directories (ASAM, The Joint Commission, Psychology Today, state registries), and external authority profiles linked through sameAs properties. There’s no published timeline, and Google decides which entities get a Knowledge Panel.
Will deploying schema actually move our AI citation rates?
Probably not on its own. Ahrefs’ May 2026 controlled test compared 1,885 pages that added schema with 4,000 that didn’t and found no major lift in AI citations on any platform. Google says no special schema is needed for AI Overviews or AI Mode.
Schema still has a job: it describes the facility, its clinicians, and its programs accurately and consistently. Microsoft says schema helps search engines and AI systems understand content, without guaranteeing selection.
The honest framing is that schema supports a strong content and entity program. It doesn’t substitute for one, so deploy it for accuracy and measure AI visibility on its own terms.
Do we need to hire a developer to deploy schema?
For basic Organization, LocalBusiness, and Article schema, no. Most WordPress sites can deploy these through SEO plugins (Yoast, Rank Math, Schema Pro) with no custom development required. The plugins generate JSON-LD that covers the foundational entity types.
For advanced schema (MedicalClinic specializations, custom knowsAbout arrays, multi-author Person schema with cross-references, FAQPage with multiple Q&A entities), some developer time is usually needed to extend the plugin output or to deploy custom schema templates. Plan for some developer time to set it up, plus ongoing maintenance as new content publishes.
For multi-location operators, schema deployment at scale benefits from a dedicated schema management tool or a custom implementation that holds consistency across location-specific pages. The cost of getting this wrong (conflicting schema between location pages, generic schema where specific schema is needed) is much higher than the cost of doing it right the first time.
How does entity SEO interact with our existing local SEO program?
Entity SEO strengthens local SEO and vice versa. The two overlap on LocalBusiness schema, geographic entity associations, and the citations across authoritative directories that build both local pack visibility and Knowledge Graph entity recognition.
Entity SEO adds a layer on top: ensuring the LocalBusiness schema on your site is specialized to MedicalClinic, declaring knowsAbout for the specific clinical topics relevant to the local market, and linking the local entity to broader authority signals through sameAs properties.
Running both keeps the same facts consistent across local listings, your site, and the sources AI systems read. Both surfaces matter for treatment centers: the local pack drives calls and visits, and AI answers shape how families first hear about you.
What is the right starting point if we are doing none of this today?
Start with the entity audit (Knowledge Panel check, schema inventory, sameAs audit, author entity check, knowsAbout audit) and prioritize the gaps. For most operators starting from zero, the right order is:
- Deploy Organization and LocalBusiness schema on the homepage and About page with full property coverage including
sameAsto LinkedIn, ASAM, and The Joint Commission - Add
knowsAboutdeclarations for the specific clinical topics the facility genuinely specializes in - Specialize the LocalBusiness schema to MedicalClinic on location pages
- Deploy Person schema for your credentialed clinical authors with consistent attribution across content
- Add MedicalSpecialty and Service schema on level-of-care pages
- Keep Article schema accurate across the content layer (FAQ and HowTo rich results are retired)
Plan the work in phases, starting with Organization and author markup. Measure AI visibility before and after, and judge results over months rather than weeks.
The perspective in this article comes from 9 years working exclusively inside behavioral health.
We are a team built by people in recovery who understand that behind every admission is someone asking for help. If that resonates, get to know us.
Trevor Gage is the Director of Earned & Owned Media at Webserv, where he leads SEO, content strategy, and organic acquisition for behavioral health treatment centers. He has overseen audits of more than 200 behavioral health sites and writes about the technical and editorial SEO standards Webserv applies to client work.