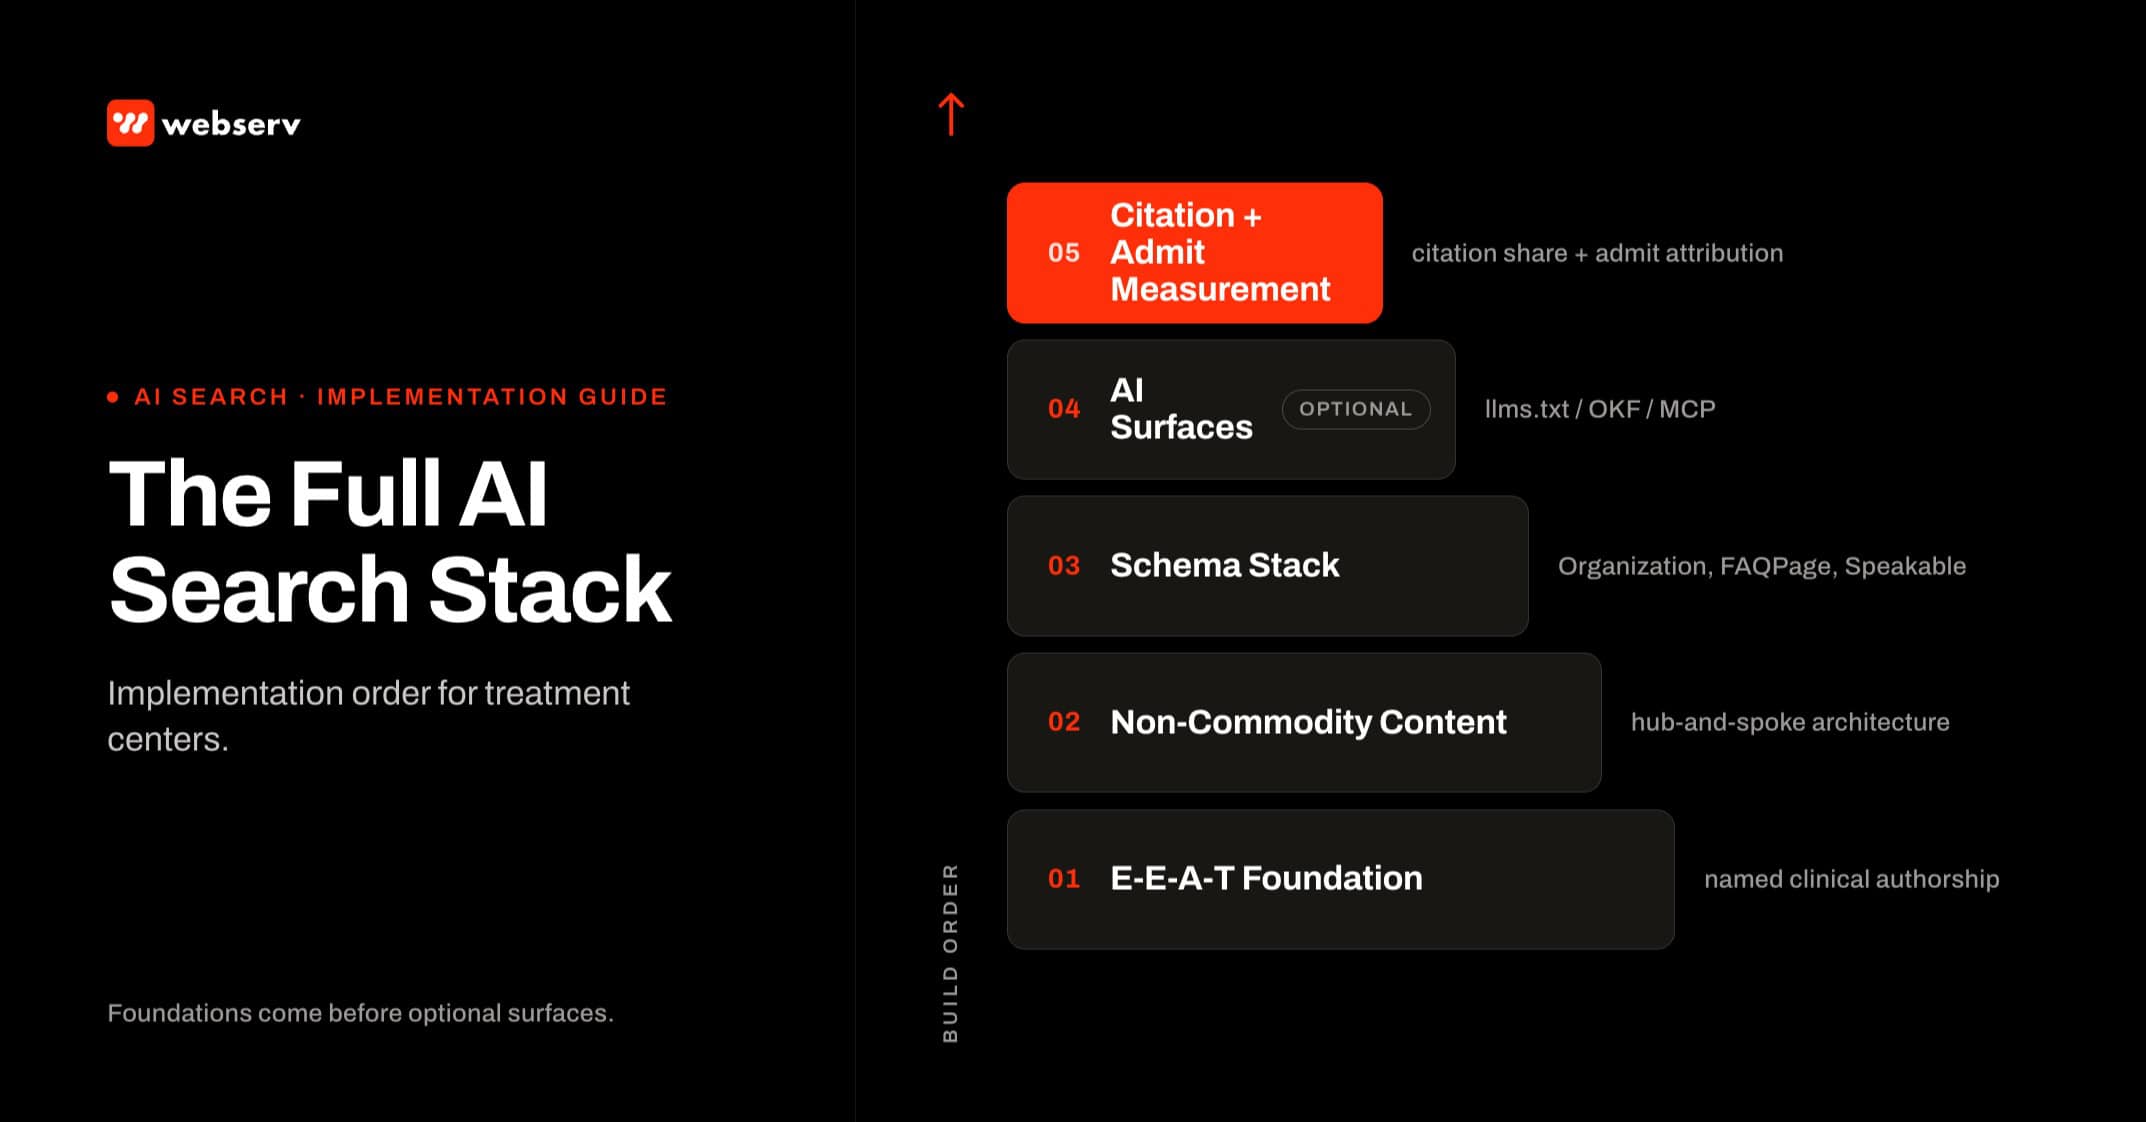
A treatment center we work with started 2026 with a question we have been getting every week since AI Overviews became unavoidable.
The marketing director had read about ChatGPT citations, schema, llms.txt, MCP servers, the Open Knowledge Format, AI Information pages, and a dozen other surfaces that newsletters and conference talks were treating as load-bearing.
The vendors pitching her each had a different “must-have.”
Her actual question was simpler. What is the full stack she needs to ship, in what order, with which trade-offs, and how does she know it is working.
This article is the answer. The full AI search stack for treatment centers, with the implementation order, the trade-offs, and the measurement layer that ties the work back to admit-attributed conversion.
The frame is built around the four phases we walk operators through inside our content SEO program for treatment centers and synthesizes what Google’s June 2026 generative AI optimization guide made explicit.
Three composite numbers below from the treatment center we used as the anchor for this guide. Each came from the same 90-day reorganization that put the stack in place.
4x
AI Overview citation share for condition-cluster queries
+31%
Admit-attributed conversion from organic traffic
0 → 8
Citations across ChatGPT, Claude, Perplexity in 90 days
The rest of this article walks the stack from foundation to measurement.
Key Takeaways
- The AI search stack for treatment centers has four phases: foundation (E-E-A-T plus technical SEO), content (non-commodity content with named clinical authorship), infrastructure (schema plus the optional AI-specific surfaces), and measurement. The phases are sequential. Skipping ahead produces less compounding lift than sequencing the work correctly.
- Per Google’s June 2026 official guidance, optimizing for generative AI search is still SEO. AI Overviews rely on Google’s core ranking systems, and the architecture that ranks well for classic organic search is the architecture that earns AI citation share. The AEO-vs-SEO frame the industry built in 2023-2024 is unified, not split.
- Named clinical authorship is non-negotiable. AI search systems weight Experience, Expertise, Authoritativeness, and Trustworthiness signals at the YMYL threshold for healthcare, and clinician-credentialed content is the load-bearing signal that separates cited sources from invisible ones.
- The optional AI-specific surfaces (llms.txt, OKF bundles, MCP servers, AI Information pages) carry weight outside Google Search even though Google says it does not use llms.txt for ranking. Operators investing in these should size the investment to the non-Google AI surface they want to influence rather than expect Google ranking lift.
- Measurement matters more than tactics. The right framework tracks citation share across at least four AI surfaces (Google AI Overviews, ChatGPT, Claude, Perplexity) and ties it back to admit-attributed conversion via 60- to 120-day attribution windows. Without measurement, the operator cannot tell which layer of the stack is producing the lift.
PHASE 1 · FOUNDATION
What “AI Search” Actually Means in 2026
Before the stack makes sense, the operator needs a shared vocabulary for what AI search systems actually do. Two technical concepts drive every architectural decision below.
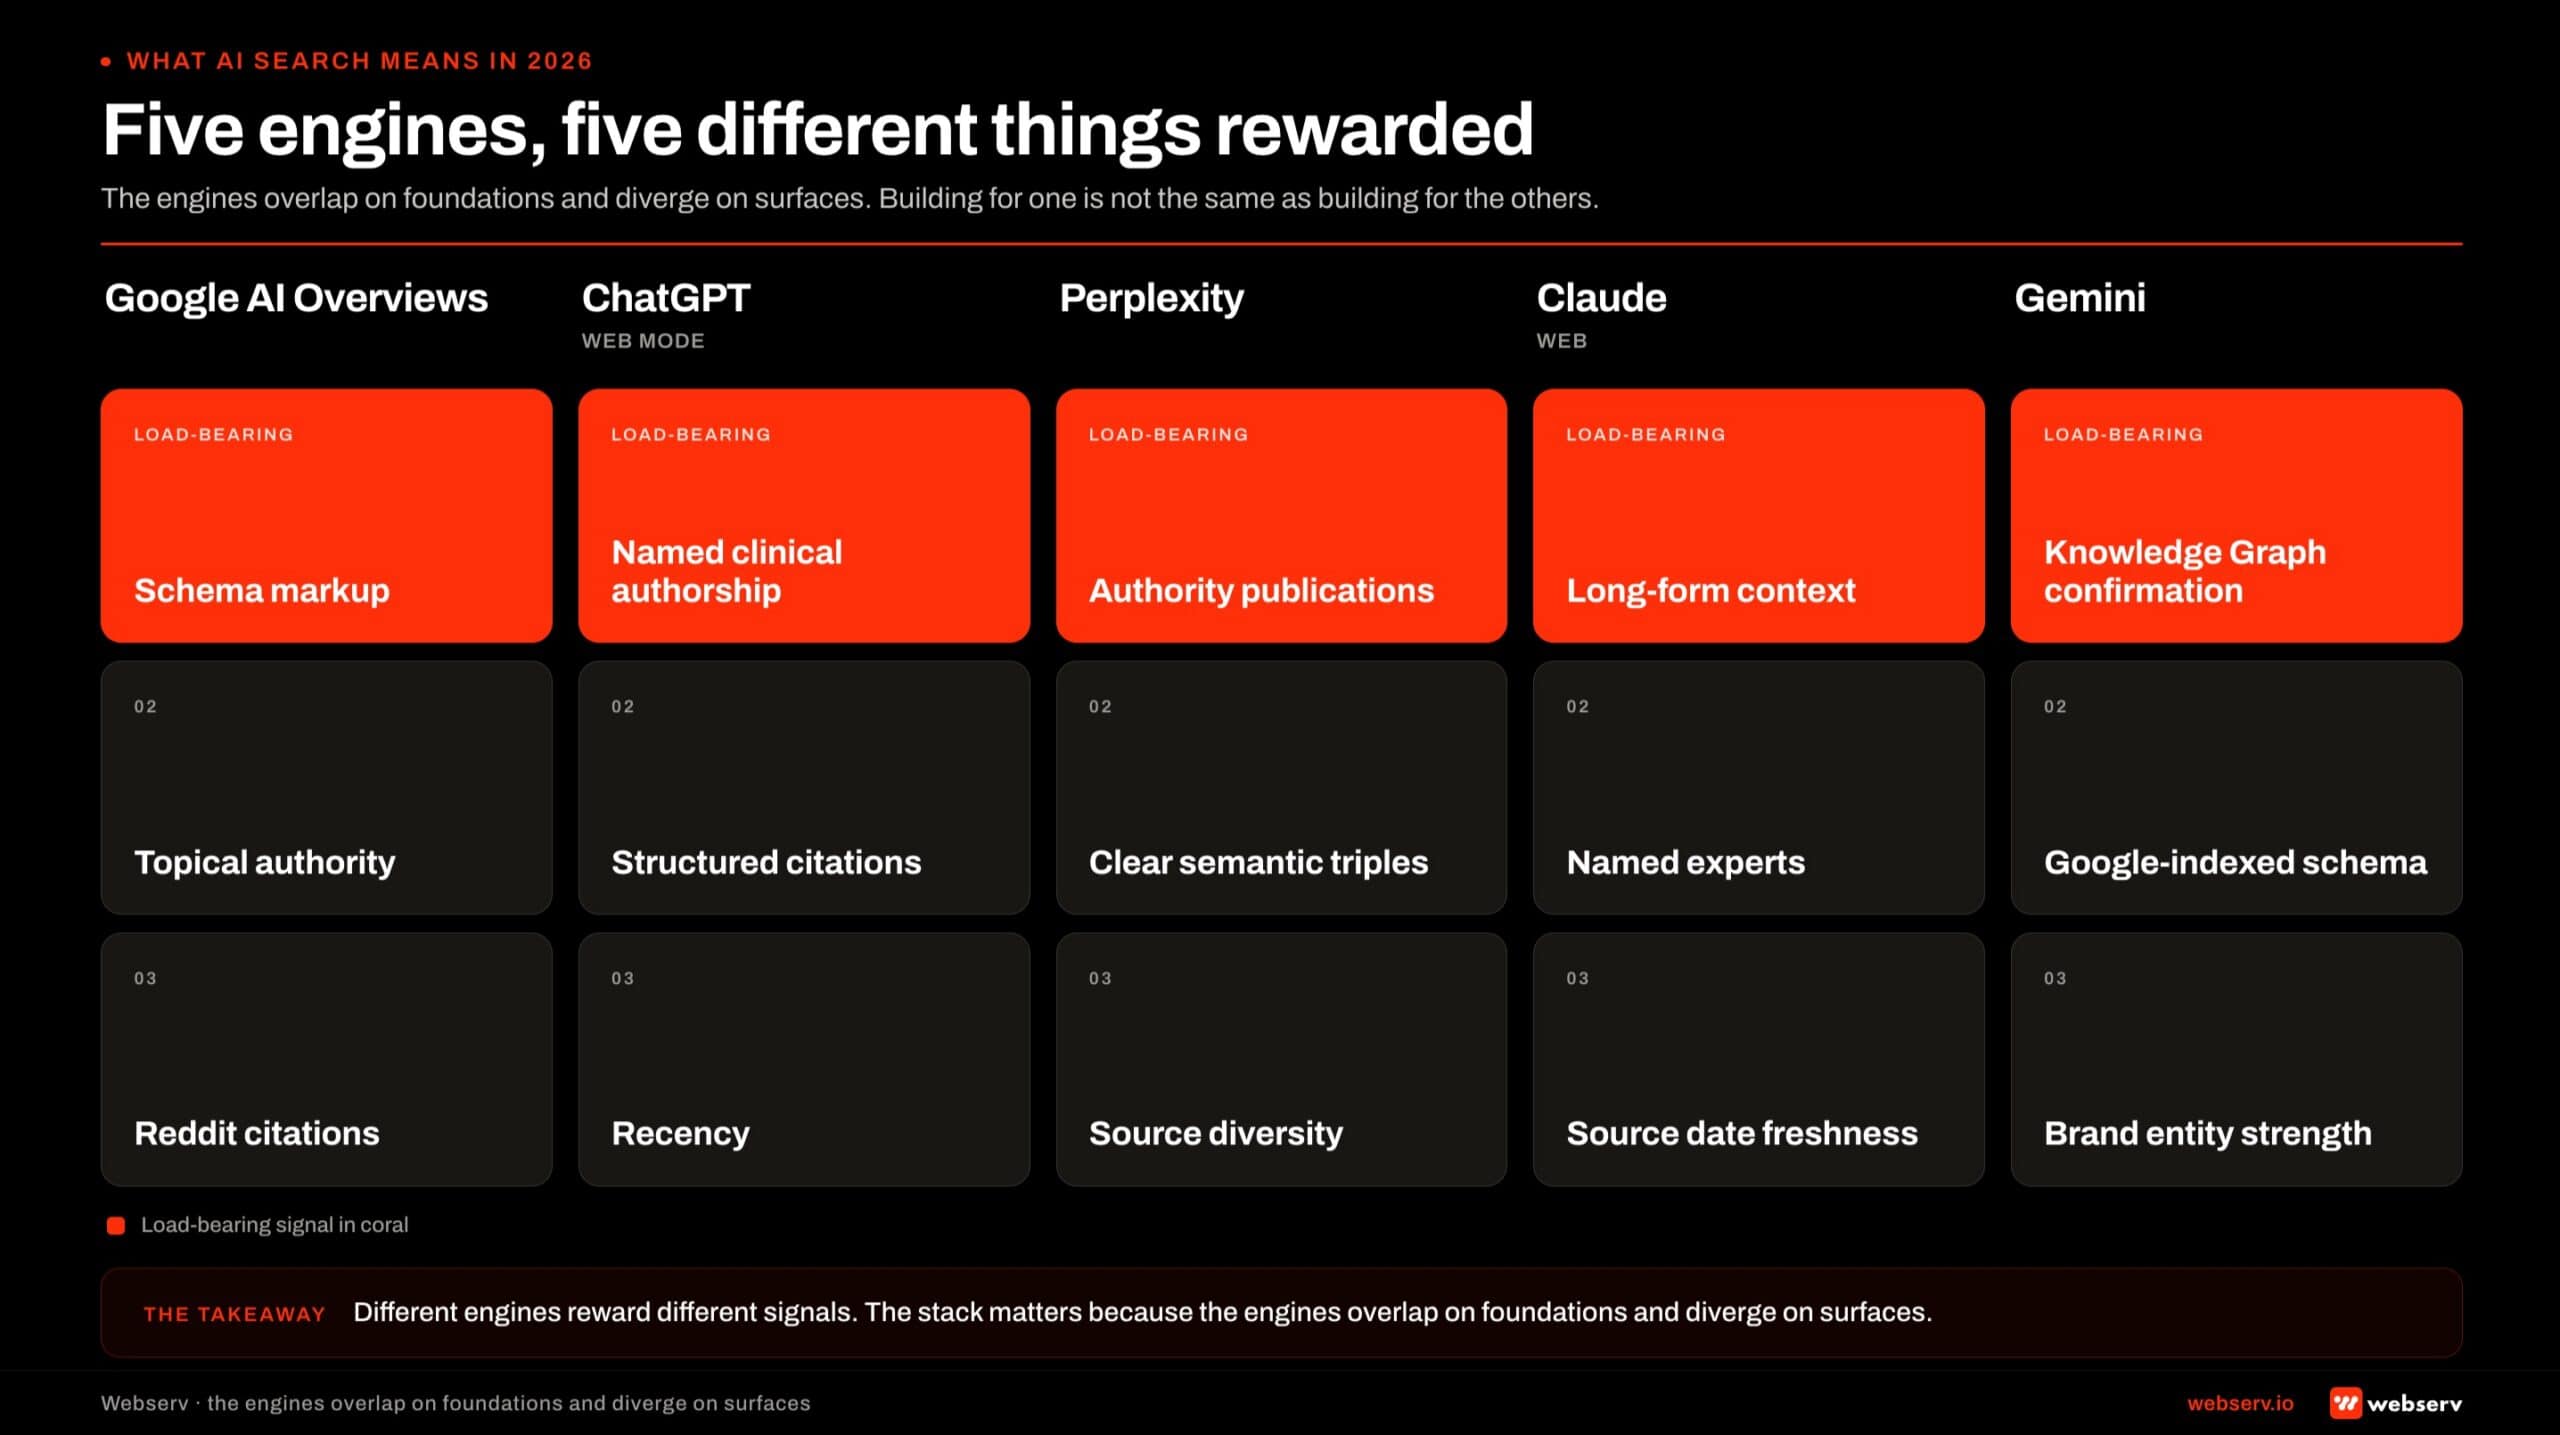 Five AI engines and the top signals each one rewards. Google AI Overviews: schema markup, topical authority, Reddit citations. ChatGPT: named clinical authorship, structured citations, recency. Perplexity: authority publications, semantic triples, source diversity. Claude: long-form context, named experts, freshness. Gemini: Knowledge Graph confirmation, Google-indexed schema, brand entity strength.
DEFINITION
Retrieval-Augmented Generation (RAG)
How AI search features ground their answers. The model pulls candidate sources from Google’s Search index, then generates a response that cites those pages. The underlying ranking systems determine which sources get retrieved.
The second mechanic is query fan-out. AI systems decompose a single user question into 6 to 15 concurrent sub-queries (interventions, MAT, family resources for a question about “fentanyl treatment for my son”), each routed through Google’s ranking. The cited sources are the union of what gets retrieved across the fan-out set.
These two mechanics explain why the AEO-vs-SEO debate ended. The model retrieves from the same index your classic organic results sit in, and the fan-out queries it runs are evaluated by the same ranking systems.
The architecture that produces strong classic organic ranking is the architecture that produces strong AI citation share.
What the AI search shift does change is the emphasis. Google’s guidance now centers on non-commodity content (experience-led perspective) over commodity content (recyclable common knowledge).
For treatment centers, this is the difference between a clinician’s first-hand reflection on co-occurring disorder assessment and a generic “what is dual diagnosis” explainer.
The first earns citation share. The second sits in the long tail of commodity content that the post-2025 systems explicitly deprioritize.
PHASE 1 · FOUNDATION
What the March 2026 core update changed for the stack
Google’s March 2026 core update materially shifted the weighting inside the AI search stack. Three specific changes matter for treatment center operators evaluating what to keep, what to strip, and where to invest fresh work.
Change 1: FAQ, Review, and HowTo schema got de-prioritized on non-primary content pages. Google reduced rich-result display for these three schema types on thin-content pages, service pages, and listicle-style content. The specific pages that lost rich-result eligibility: service pages with FAQ schema stapled to the bottom, blog posts where the FAQ block was the primary content asset, and any page where FAQ schema was carrying more of the ranking weight than the underlying content. Google’s Search Central documentation for FAQPage rich results now explicitly ties eligibility to primary content depth.
FAQ schema on primary content pages (comprehensive ultimate guides, cluster hubs, deep how-to content) retained rich-result eligibility. The specific fix for treatment centers: audit the FAQ block deployment across the corpus and strip FAQ schema from thin pages while keeping it on primary content. Our FAQ schema after March 2026 piece walks the 5-minute audit and the Q&A rewrite pattern for AI extraction.
Change 2: Fact density elevated as a ranking signal. The March 2026 update reweighted content quality signals to favor pages with high concentration of verifiable facts (numbers, dollar amounts, proper nouns, parenthetical specifics, dated ranges) over pages with generic marketing language.
The specific measurement: pages averaging 3+ verifiable facts per 100 words typically produce 2 to 3x higher AI citation rates than pages averaging under 1 fact per 100 words.
Behavioral health content that lists specific payer names, specific rate spreads, specific timelines, and specific compliance rules typically clears the fact-density threshold that AI systems reward.
Change 3: Content refresh cadence became an explicit signal. Content updated in the past 3 months averages 6 AI citations versus 3.6 for outdated content according to industry measurement. Google’s ranking algorithm and the third-party AI answer surfaces (ChatGPT, Claude, Perplexity, Bing Copilot) all factor recency into their extraction and citation decisions. Independent GEO research (see the Aggarwal et al 2023 paper and its 2024-2025 updates) documents the same pattern across academic measurement.
The specific implication for treatment centers: quarterly refresh cadence on cluster hubs and primary content pages, with visible last-updated timestamps that make the recency signal explicit. Pages published 12 to 24 months ago without refresh typically show measurable AI citation decay.
The specific work these changes trigger: (a) FAQ block audit across the corpus per our FAQ schema after March 2026 piece, (b) fact-density scoring pass on primary content pages using the 40-word answer block pattern documented in our answer block placement piece, (c) quarterly refresh calendar for hubs and top-performing pages, tracked against Google’s Search Status Dashboard for update-day context.
The E-E-A-T Foundation Every AI Search Surface Requires
Healthcare YMYL pages face the strictest E-E-A-T threshold of any vertical Google evaluates. The same threshold flows through to AI Overviews, ChatGPT, Claude, and Perplexity because those systems use Google’s ranking signals as part of their source-selection logic.
For the deep-dive on the single signal driving the most citation lift inside E-E-A-T (named clinician quotes), see Clinicians as the AEO Moat: Why Author Quotes Beat Generative AI.
For treatment centers, the foundation has four load-bearing pieces. First, named clinical author bylines on every YMYL article (not “Editorial Team,” not a generic facility staff attribution). Second, named clinical reviewer credit on top of the author byline.
Third, structured author bio pages with credentials, licensure, NPI sameAs links, and a list of authored articles. Fourth, peer-reviewed citations to SAMHSA, NIDA, NIMH, JAMA Psychiatry, and ASAM publications inside the content body.
The author and reviewer pattern is the single most common foundation gap we see. The deeper read lives in how to build clinical content Google trusts and patients actually find and author bios that build E-E-A-T for behavioral health blogs.
Without this foundation, the rest of the stack is publishing into a vacuum.
The technical SEO foundation matters alongside the E-E-A-T layer. Crawlability, schema, internal linking, Core Web Vitals, and site speed all feed into the same ranking systems. For facilities launching from zero, we walk through this sequence in the infrastructure phase for new treatment centers.
A treatment center site failing Core Web Vitals on mobile competes against a passing competitor at a structural disadvantage in both classic and AI search, regardless of how strong the E-E-A-T signals are.
PHASE 2 · CONTENT LAYER
Non-Commodity Content and Named Clinical Authorship
The content layer is where Google’s June 2026 framing matters most. The official guidance contrasts “7 Tips for First-Time Homebuyers” (commodity, recyclable from common knowledge) against “Why We Waited Five Years to Buy a House” (non-commodity, experience-led, irreducible to public information).
For treatment center content, the same distinction governs whether an article earns citation share or disappears into the long tail.
The commodity-vs-non-commodity test is concrete. Could an AI model write this article from public information alone? If yes, the article is commodity. If no, the article carries the kind of first-hand experience signal both Google and the LLMs explicitly reward.
Named clinician perspective is one of the most reliable ways to make content non-commodity.
The architectural implication runs across the editorial calendar. Articles built primarily to capture keyword variations get categorized as scaled content abuse and produce ranking drag. Articles built around named clinical voice and irreducible operational experience compound.
The cadence question matters less than the perspective question.
COMMON MISTAKE
Producing 8 articles a month with Editorial Team bylines and assuming volume produces ranking. The 184-post commodity library is the most common content footprint we audit, and it correlates with materially worse AI citation share than a 30-post library built around named clinician perspective.
The 8-article-a-month cadence is the trap. The 4-to-6-article-a-month cadence anchored in named clinician perspective is the pattern that compounds.
PHASE 2 · CONTENT LAYER
The Hub-and-Spoke Architecture Updated for AI Search
The hub-and-spoke content architecture remains the dominant pattern for treatment center websites, and the 2026 form retains the core structure with adjustments for how RAG and query fan-out actually retrieve.
The mechanic underneath hub-and-spoke is topical authority : the breadth-and-depth signal that determines whether AI engines treat your site as the authoritative source on a topic.
The five hub categories that anchor admit-driving architecture: condition pillars (alcohol use disorder, opioid use disorder, anxiety, depression, co-occurring, eating disorders) and modality clusters (CBT, DBT, EMDR, medication management, group therapy).
The architecture also covers level-of-care pages (detox, residential, PHP, IOP, outpatient), geographic anchors tied to real facility presence, and the family-facing resource hub.
A hub page runs 2,500 to 6,000 words, anchored by a named clinical author and reviewer, and serves both the human reader and the RAG retrieval pattern.
Spokes orbit each hub, addressing more specific questions inside the cluster with 1,200 to 2,800 word articles that link back to the hub and to relevant cross-cluster spokes.
Internal linking density across the cluster produces the topical authority signal Google’s ranking system rewards and that AI search systems read through to citation eligibility.
The cluster effect compounds across the four phases. A condition pillar with named authorship, peer-reviewed citations, strong schema, and internal links to 8 to 12 spokes earns AI citation share at higher rates than the same pillar in isolation.
The architecture is the multiplier. The deeper read on the full hub-and-spoke reorganization sits in our blog and resource architecture that drives rehab admissions playbook.
PHASE 3 · INFRASTRUCTURE
Brand mention weighting is now near-parity with backlinks
The industry consensus through Q1 2026 was that backlinks remained the dominant off-site ranking signal. The Q2 and Q3 2026 measurement shifted that consensus. Brand mentions across authoritative third-party sources now carry weighting approaching parity with traditional backlinks for AI search citation and Google’s own ranking.
What counts as a brand mention. Named references to the facility or the parent brand across authoritative sources (industry publications, professional association materials, academic literature, government resource pages, high-authority news coverage) even without a hyperlink to the facility website. The AI systems parse the mention, resolve the entity through knowledge graph lookup, and factor the mention into the facility’s authority signal.
Why the shift happened. 85 percent of AI brand mentions originate from third-party sources rather than the facility’s own website. AI systems weight the third-party mention differently than the facility’s own content because the third-party mention functions as external validation of the facility’s existence and positioning. The mention pattern parallels how academic citation counts function in research authority measurement.
What treatment centers should do. Three specific patterns produce brand mention volume without violating anti-kickback or advertising compliance rules. First: original research publication that gets cited by industry press and academic sources (using primary data from sources like SAMHSA’s national data collection or facility-specific outcome measurement). Second: named clinician thought leadership through professional association publications and industry conference presentations. Third: contributed content in industry publications and podcasts under named author or clinician byline.
The specific pattern that fails: paid brand mention services and directory farms that produce inauthentic mentions from low-authority sources. AI systems and Google’s ranking both filter these out, and the mentions produce no attribution lift while carrying compliance risk.
How to measure brand mention weight. Brand Radar and similar AI citation tracking tools surface the specific third-party sources citing the facility across AI answer surfaces. The measurement pattern: quarterly audit of brand mention citations, segmented by source authority, with tracking of which mentions correlate with AI citation lift on facility content. Our Reddit strategy for AEO citations piece covers the specific pattern for building brand mention volume through community engagement.
The Schema Stack That Makes Content Legible
Structured data is the technical infrastructure that helps Google’s ranking systems and AI surfaces disambiguate entities, attribute authorship, and surface FAQ content correctly. Google’s June 2026 guidance specifically calls out that the standard schema.org stack is what ranking systems use.
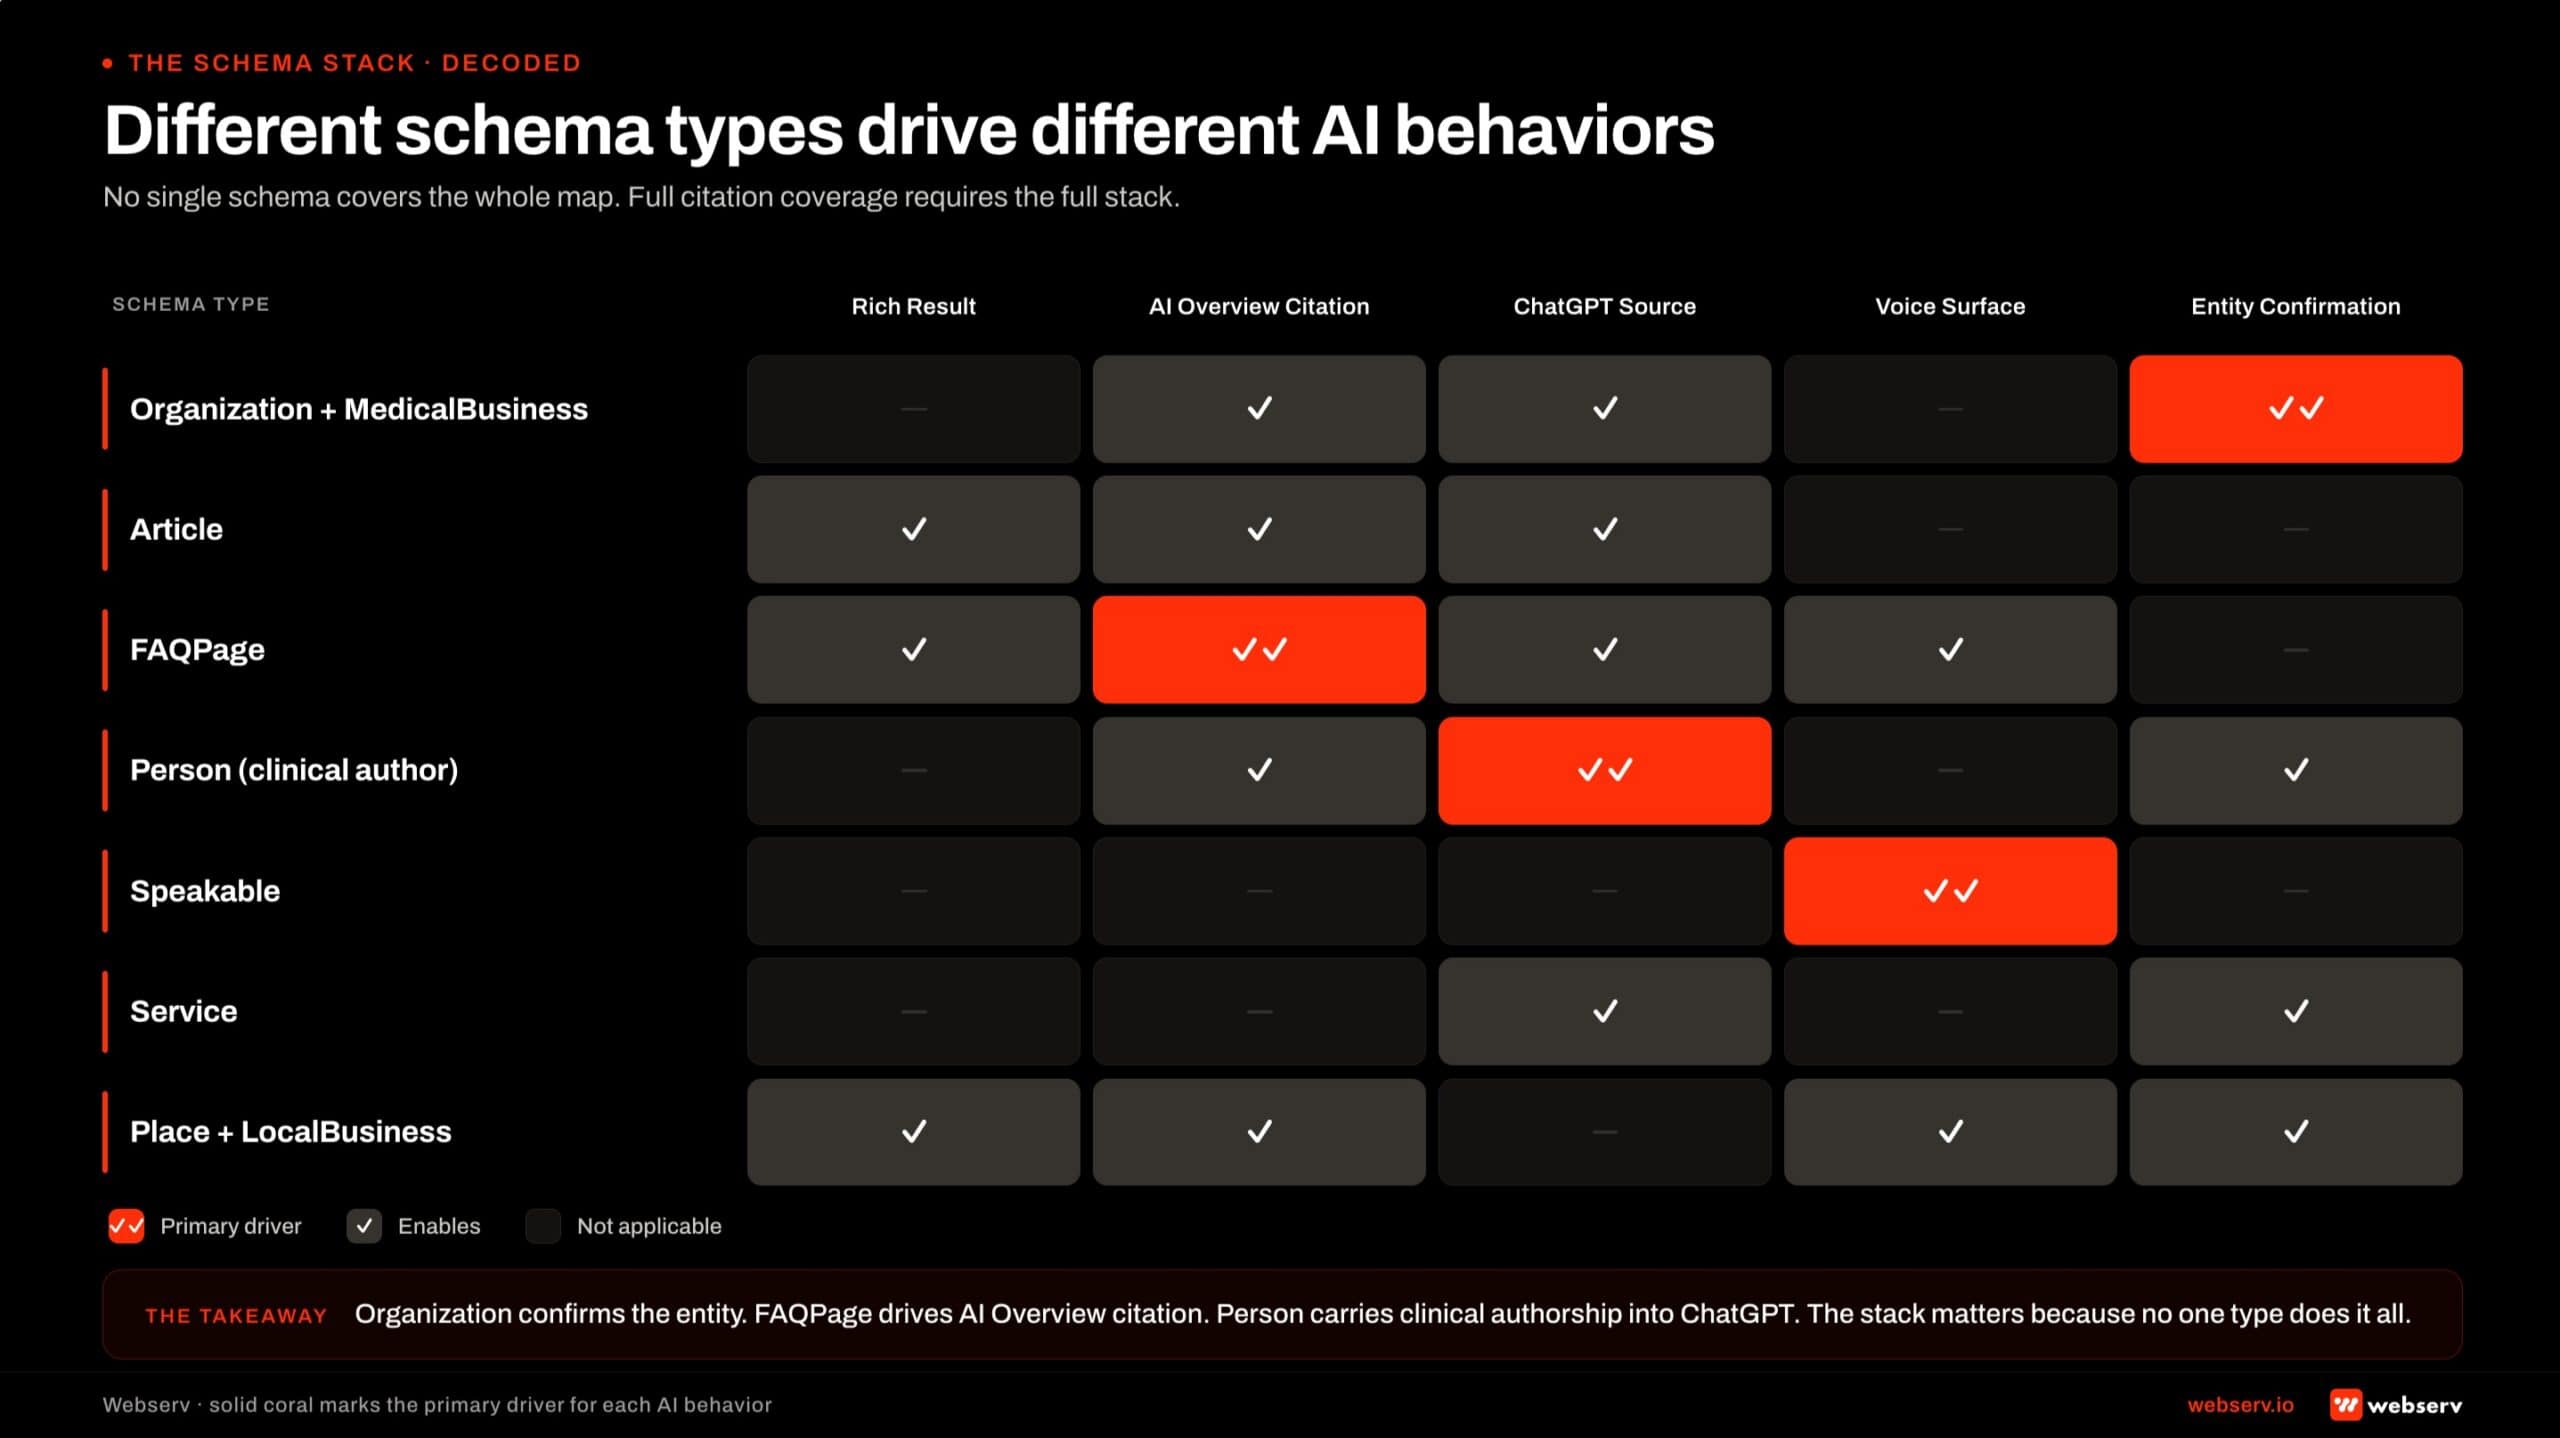 Matrix showing which schema types power which AI search behaviors. Organization and MedicalBusiness drive entity confirmation. FAQPage drives AI Overview citation. Person schema drives ChatGPT clinical-author citation. Speakable drives voice surfaces. No single schema covers all five behaviors — the stack is the answer.
For treatment centers, four schema types earn their keep.
Organization and MedicalOrganization schema deployed sitewide with a stable @id, anchoring the facility’s entity in Google’s knowledge graph. Article schema with Person author and Organization publisher on every clinical content piece.
FAQPage schema on articles with FAQ blocks, earning featured snippet eligibility. BreadcrumbList schema across the cluster, supporting navigational legibility.
The pattern Google’s guidance specifically deprioritizes is speculative AI-only schema. Custom schema types designed to “help AI systems understand the content” beyond standard schema.org do not produce ranking lift and can flag content as over-optimized.
Operators investing heavily in AI-specific schema work in 2024 and 2025 sometimes overbuilt this layer. The right read in 2026 is to keep the standard schema stack mature and stop there.
PHASE 3 · INFRASTRUCTURE
The Optional AI-Specific Surfaces: AI Information Page, llms.txt, OKF, MCP
The next layer in the stack covers the AI-specific surfaces that emerged after AI Overviews launched. Four surfaces matter for treatment center operators evaluating where to invest.
The AI Information page is a canonical brand-facts page designed for LLM citation accuracy. Structured, label-value formatted, with the facility’s name, founding date, leadership team, accreditations, services, locations, and the relationships between them.
The page is human-readable and crawler-readable. AI systems use it to verify facts about the facility when generating responses.
The pattern is well-established and produces measurable citation accuracy lift across non-Google AI surfaces.
llms.txt is a plain-text site overview at the root of the domain, designed to give AI crawlers a quick orientation to the site. The format is simple and widely discussed in AEO industry conversations.
POSITION UPDATE
Google’s June 2026 documentation clarified what we and most AEO practitioners had treated as an open question. The official quote: “Doing so won’t harm (nor help) your visibility or rankings in Google Search.” That refines the read for ranking. The same Google in May 2026 added a Lighthouse Agentic Browsing audit (default in PageSpeed Insights as of May 21, 2026) that scores three checks including a valid llms.txt at the domain root. Google Search ignores it for ranking, but Google’s own developer tooling now scores against it as an agent-readiness signal. Ship it.
The Open Knowledge Format (OKF) is the markdown-plus-YAML bundle format Google Cloud published in June 2026. The format provides a relational layer (this service connects to this case study, which connects to this clinical author) that goes deeper than llms.txt or standard schema.
Like llms.txt, OKF does not produce Google Search ranking lift directly, but it serves as the AI-agent-readable knowledge graph for non-Google surfaces.
We published one of the first OKF bundles in behavioral health marketing. The deeper read lives in our analysis of the Open Knowledge Format for treatment centers.
DEFINITION
MCP server (Model Context Protocol)
A callable API that lets AI agents query a facility’s data on demand. Where OKF is static (a published knowledge graph), MCP is dynamic (a queryable interface). Useful for facilities expecting agent-driven traffic over the next 24 months.
The MCP server sits at the highest end of the AI-specific surface stack. The implementation is more technical than llms.txt or OKF and requires development capacity that most treatment center operators do not currently have in-house.
Operators serious about the agentic-search horizon should consider an MCP server. Operators focused on the next 12 months of conventional AI Overviews and assistant citations can defer it.
The combined investment in the four AI-specific surfaces typically runs $8,000 to $25,000 in implementation cost, with ongoing maintenance minimal once shipped.
The right read on the investment is asymmetric: the cost is bounded, the upside compounds if AI search behaviors evolve as projected, and the downside is small if they do not.
PHASE 4 · MEASUREMENT
How SoCal Sunrise generated 85 admissions and 2,297% ROI from SEO in 6 months
A ground-up SEO rebuild using the Pathfinder Parents Methodology turned an invisible online presence into a top-ranking admissions engine.
Read the case study →85 admits and 3,152 leads attributed to organic
Bing Copilot as the fifth tracked surface. Bing Copilot became a materially larger citation source through 2026 as Microsoft integrated the AI answer surface across Bing search, Edge browser search, and Windows Copilot experiences. The specific extraction pattern for Bing Copilot: Bing’s crawl and index feed the underlying source pool, with Microsoft’s AI answer overlay pulling from Bing-indexed sources. Facilities that maintain strong Bing search visibility (through Bing Webmaster Tools submission, Bing sitemap ping, and Bing-specific SEO signals) produce meaningfully higher Bing Copilot citation rates than facilities focused only on Google organic and Google AI Overviews. Treat Bing Copilot as the fifth AI-specific surface alongside ChatGPT, Claude, Perplexity, and Google AI Overviews when scoping the surface stack.
How to Track AI Citation Share Across Surfaces
Measurement is what separates the operators producing durable AI search lift from the operators running tactical experiments and hoping. The right framework tracks citation share across at least four AI surfaces.
The 3-step measurement setup most operators implement.
Baseline citation share
Run priority queries through ChatGPT, Claude, Perplexity, and Google AI Overviews. Document which sources get cited for each query.
Implement the stack
Ship the foundation, content, and infrastructure phases. Update the baseline measurement quarterly with the same query set.
Tie to admit attribution
Connect AI-search-driven visits to admit-attributed conversion in the CRM with 60- to 120-day attribution windows.
The baseline-citation-share step matters most. Operators who skip it cannot tell whether their AI citation work produced lift or whether they would have ranked the same without it.
The baseline can be manually compiled in a spreadsheet or, for larger operators, via Profound or one of the emerging AI citation tracking tools.
The quarterly review cadence is the right rhythm. AI citation behaviors shift faster than classic organic ranking shifts, but not so fast that monthly tracking adds signal. The quarterly review surfaces real movement and filters out noise.
PHASE 4 · MEASUREMENT
Brand Radar citation tracking
The specific tool category that emerged for tracking AI citations across surfaces is dedicated citation trackers like Brand Radar, Otterly, and similar platforms. These tools query the specific AI answer surfaces (ChatGPT, Claude, Perplexity, Google AI Overviews, Bing Copilot) with target prompts and record which sources get cited in each answer. The measurement pattern: monthly audit of target prompts with citation share tracked by AI surface. Facilities that measure citation share monthly typically detect ranking shifts 30 to 60 days before the shifts appear in traditional organic search metrics. Bing Copilot has become a materially larger citation source through 2026 as Microsoft integrated the AI answer surface across Bing search, Edge browser search, and Windows Copilot experiences, and should be tracked alongside the other four surfaces.
Content refresh cadence signal
Content updated in the past 3 months averages 6 AI citations versus 3.6 for outdated content. The specific measurement: visible last-updated timestamps on cluster hubs and primary content pages that both Google’s ranking and third-party AI surfaces factor into extraction decisions. The refresh cadence pattern that works: cluster hubs refreshed quarterly, primary content pages refreshed semi-annually, and supporting content refreshed annually or when the underlying facts change materially. Independent GEO research (see the Aggarwal et al GEO methodology paper) documents recency as one of the specific extraction signals AI systems weight.
Fact-density scoring
The March 2026 core update elevated fact density as a ranking signal. The specific measurement: verifiable facts per 100 words (numbers, dollar amounts, proper nouns, parenthetical specifics, dated ranges). Pages averaging 3+ facts per 100 words typically produce 2 to 3x higher AI citation rates than pages averaging under 1 fact per 100 words. The scoring pattern: run fact-density audit on cluster hubs and primary content quarterly, rewrite low-density pages to add specific facts, and preserve high-density pages against dilution during editorial passes. The specific tactical implementation for treatment center pages is documented in our 40-word answer block piece — the answer-block extraction unit under every H2 is where fact density most directly translates to AI citation lift.
From Citation to Admit Attribution
Citation share is the upstream metric. Admit attribution is the metric that pays the bills. The connection between the two is what justifies the investment in the full stack.
The attribution pattern works in three layers. AI-search-driven visits to the facility’s site (tracked through referrer data, UTM tags where applicable, and direct-traffic uplift signals when an AI citation appears for a query the facility ranks for).
Inquiry conversions from those visits (tracked through call tracking, form submissions, and chat). Admits traced back through the CRM with 60- to 120-day windows that match the BH conversion cycle.
The measurement is not as clean as paid media attribution. AI surfaces do not always pass referrer data. Direct traffic uplift after an AI citation appears can take 30 to 60 days to materialize as the citation pattern stabilizes.
The right read is to use AI citation share as a leading indicator and admit attribution as the lagging confirmation, rather than expecting attribution to be deterministic per AI surface.
The Google AI Overviews and ChatGPT citation playbook covers the broader citation strategy frame. This article is the measurement context that sits underneath.
PHASE 4 · MEASUREMENT
Common Implementation Mistakes
The pattern across every treatment center AI search audit we run is consistent. Operators consistently get either the foundation right and the infrastructure wrong, or the infrastructure right and the foundation wrong, but rarely both right.
The strongest implementations across our client base come down to a small set of behaviors operators consistently get right or wrong.
WHAT WORKING AI SEARCH STACKS DO
- Named clinical author and reviewer on every YMYL article
- Hub-and-spoke architecture with deliberate internal linking
- Non-commodity content built on first-hand clinical perspective
- Quarterly AI citation share baseline + admit attribution
- AI-specific surfaces sized to the non-Google AI horizon
WHAT BROKEN AI SEARCH STACKS SKIP
- Editorial Team bylines on YMYL content
- Chronological /blog/ feed with no hub pages
- Commodity 7-Tips and listicle content
- No citation tracking, no attribution windows
- llms.txt and OKF expected to lift Google ranking
Most facilities have two or three of these mistakes in their current implementation. Closing them in sequence produces the compounding lift the stack is designed to deliver.
The order matters: foundation first, content second, infrastructure third, measurement fourth. Reversing the order or skipping the foundation produces 12 months of tactical work with no measurable lift.
Most in-house teams hit a wall not because they lack knowledge, but because they lack bandwidth.
When you are ready to hand it off, Webserv has spent 9 years executing exactly this for treatment centers nationwide.
Frequently Asked Questions
Where should an operator start if they have not done any of this work yet?
Start with the foundation phase. E-E-A-T (named clinical authorship, structured author bios, peer-reviewed citations) plus the technical SEO baseline (Core Web Vitals, schema, internal linking) are the layers everything else compounds on. Operators who skip the foundation and start with llms.txt or OKF produce expensive surface work that does not have content to point at.
The first 30 days should rebuild author bylines and reviewer credit across the existing library. The next 30 days should ship the schema stack (Organization, MedicalOrganization, Article with Person author, FAQPage, BreadcrumbList). After that, the content layer compounds for the next 6 to 12 months and the infrastructure surfaces become net-additive rather than load-bearing.
The sequencing matters more than the speed. A facility that ships foundation by month 3, content cluster expansion by month 9, and full infrastructure by month 12 outperforms a facility that tries to ship all four phases in parallel at month 1.
How long does the full stack take to produce results?
First measurable lift typically shows up at 60 to 90 days as the foundation phase lands. Cluster-wide AI citation share movement lands at 6 to 9 months as the content layer compounds. Admit-attributed conversion lift lands at 9 to 18 months as the full stack matures and the CRM attribution windows catch up.
The compounding effect is non-linear. The first 6 months produce roughly 30 percent of the total lift the stack will eventually deliver. The next 12 months produce the remaining 70 percent as the architecture is in place and the new content publishes into a strong foundation. Operators who quit at month 6 because the early lift looks modest miss the compounding curve entirely.
The right framing is 18 to 24 months for a full stack maturation. The work is durable once landed, but the timeline is not compressible without skipping phases.
Should an operator invest in llms.txt and OKF if Google does not use them for ranking?
Yes, but size the investment to the non-Google AI surface they actually influence. Google’s June 2026 guidance confirmed Google Search does not use llms.txt for ranking. ChatGPT, Claude, Perplexity, and emerging AI agents still read these surfaces, and citation share on those platforms is a growing share of high-intent treatment center traffic.
The combined investment in AI Information page + llms.txt + OKF + MCP server typically runs $8,000 to $25,000 in implementation cost. That cost is bounded. The upside compounds if AI search behaviors evolve as projected (more agentic, more retrieval-based, more cross-platform). The downside is small if they do not.
For most treatment center operators in the $50K to $250K monthly marketing spend range, the asymmetric payoff justifies the investment as long as it does not displace foundation work or content production cadence.
What’s the difference between an AI Information page and llms.txt?
The AI Information page is a human-readable, crawler-readable web page that disambiguates the facility’s identity (name, founding date, leadership, accreditations, services, locations). It sits at a URL on the site and is designed for AI systems to cite when generating responses about the facility. Operators control the content directly.
llms.txt is a plain-text site overview file at the root of the domain (mysite.com/llms.txt). Its job is to give AI crawlers a quick orientation to the site’s content structure, similar in spirit to robots.txt but for content navigation. It is shorter, more abstracted, and not a substitute for the AI Information page’s factual depth.
Operators ship both. The AI Information page is the factual source for entity disambiguation. llms.txt is the navigational hint for crawlers. They serve different jobs and the investment in each is small enough that picking one over the other does not change the economics.
How does this work with the existing paid media program?
The AI search stack is the organic counterpart to the paid media program, and the two compound when both are mature. Strong organic citation share lowers branded-query CPCs in paid (the facility shows up in Google AI Overviews for the same queries, reducing the perceived need to click on a paid ad). Strong paid conversion infrastructure makes organic traffic convert at the same rates paid traffic does.
The investment ratio depends on facility stage. New facilities (under 18 months of marketing maturity) should bias toward paid for early admits while the organic stack matures. Established facilities (3+ years of marketing maturity) typically run organic and paid at parity and use the compounding organic asset as the moat.
The wrong pattern is treating organic and paid as competing budgets. They serve different funnel positions and the combined ROI is materially higher than either in isolation. The right framing is ‘paid for the next 30 days, organic for the next 30 months.’
What about MCP servers and agentic search?
MCP (Model Context Protocol) servers are the highest-end surface in the stack and the most speculative investment. The thesis is that AI agents in the next 24 months will increasingly query facility data directly (insurance verification, bed availability, level-of-care fit) rather than read static pages. An MCP server is the callable interface that lets agents do that.
Operators serious about the agentic-search horizon should consider one. The implementation is more technical than llms.txt or OKF and typically requires developer capacity, which puts it out of reach for smaller facilities without an existing technical partner. Most current treatment center operators can defer the MCP investment for 12 to 18 months without missing the window.
The exception is facilities with strong technical capacity and a forward-looking marketing posture. For them, shipping an MCP server now is cheap insurance against the agentic-search shift and produces a differentiated infrastructure signal that competitors will not match for some time.
Ship the Foundation Before the Surfaces
The full AI search stack is real work. Four phases, sequenced, each compounding on the last. The operators producing durable lift are the operators who ship foundation first, then content, then infrastructure, then measurement.
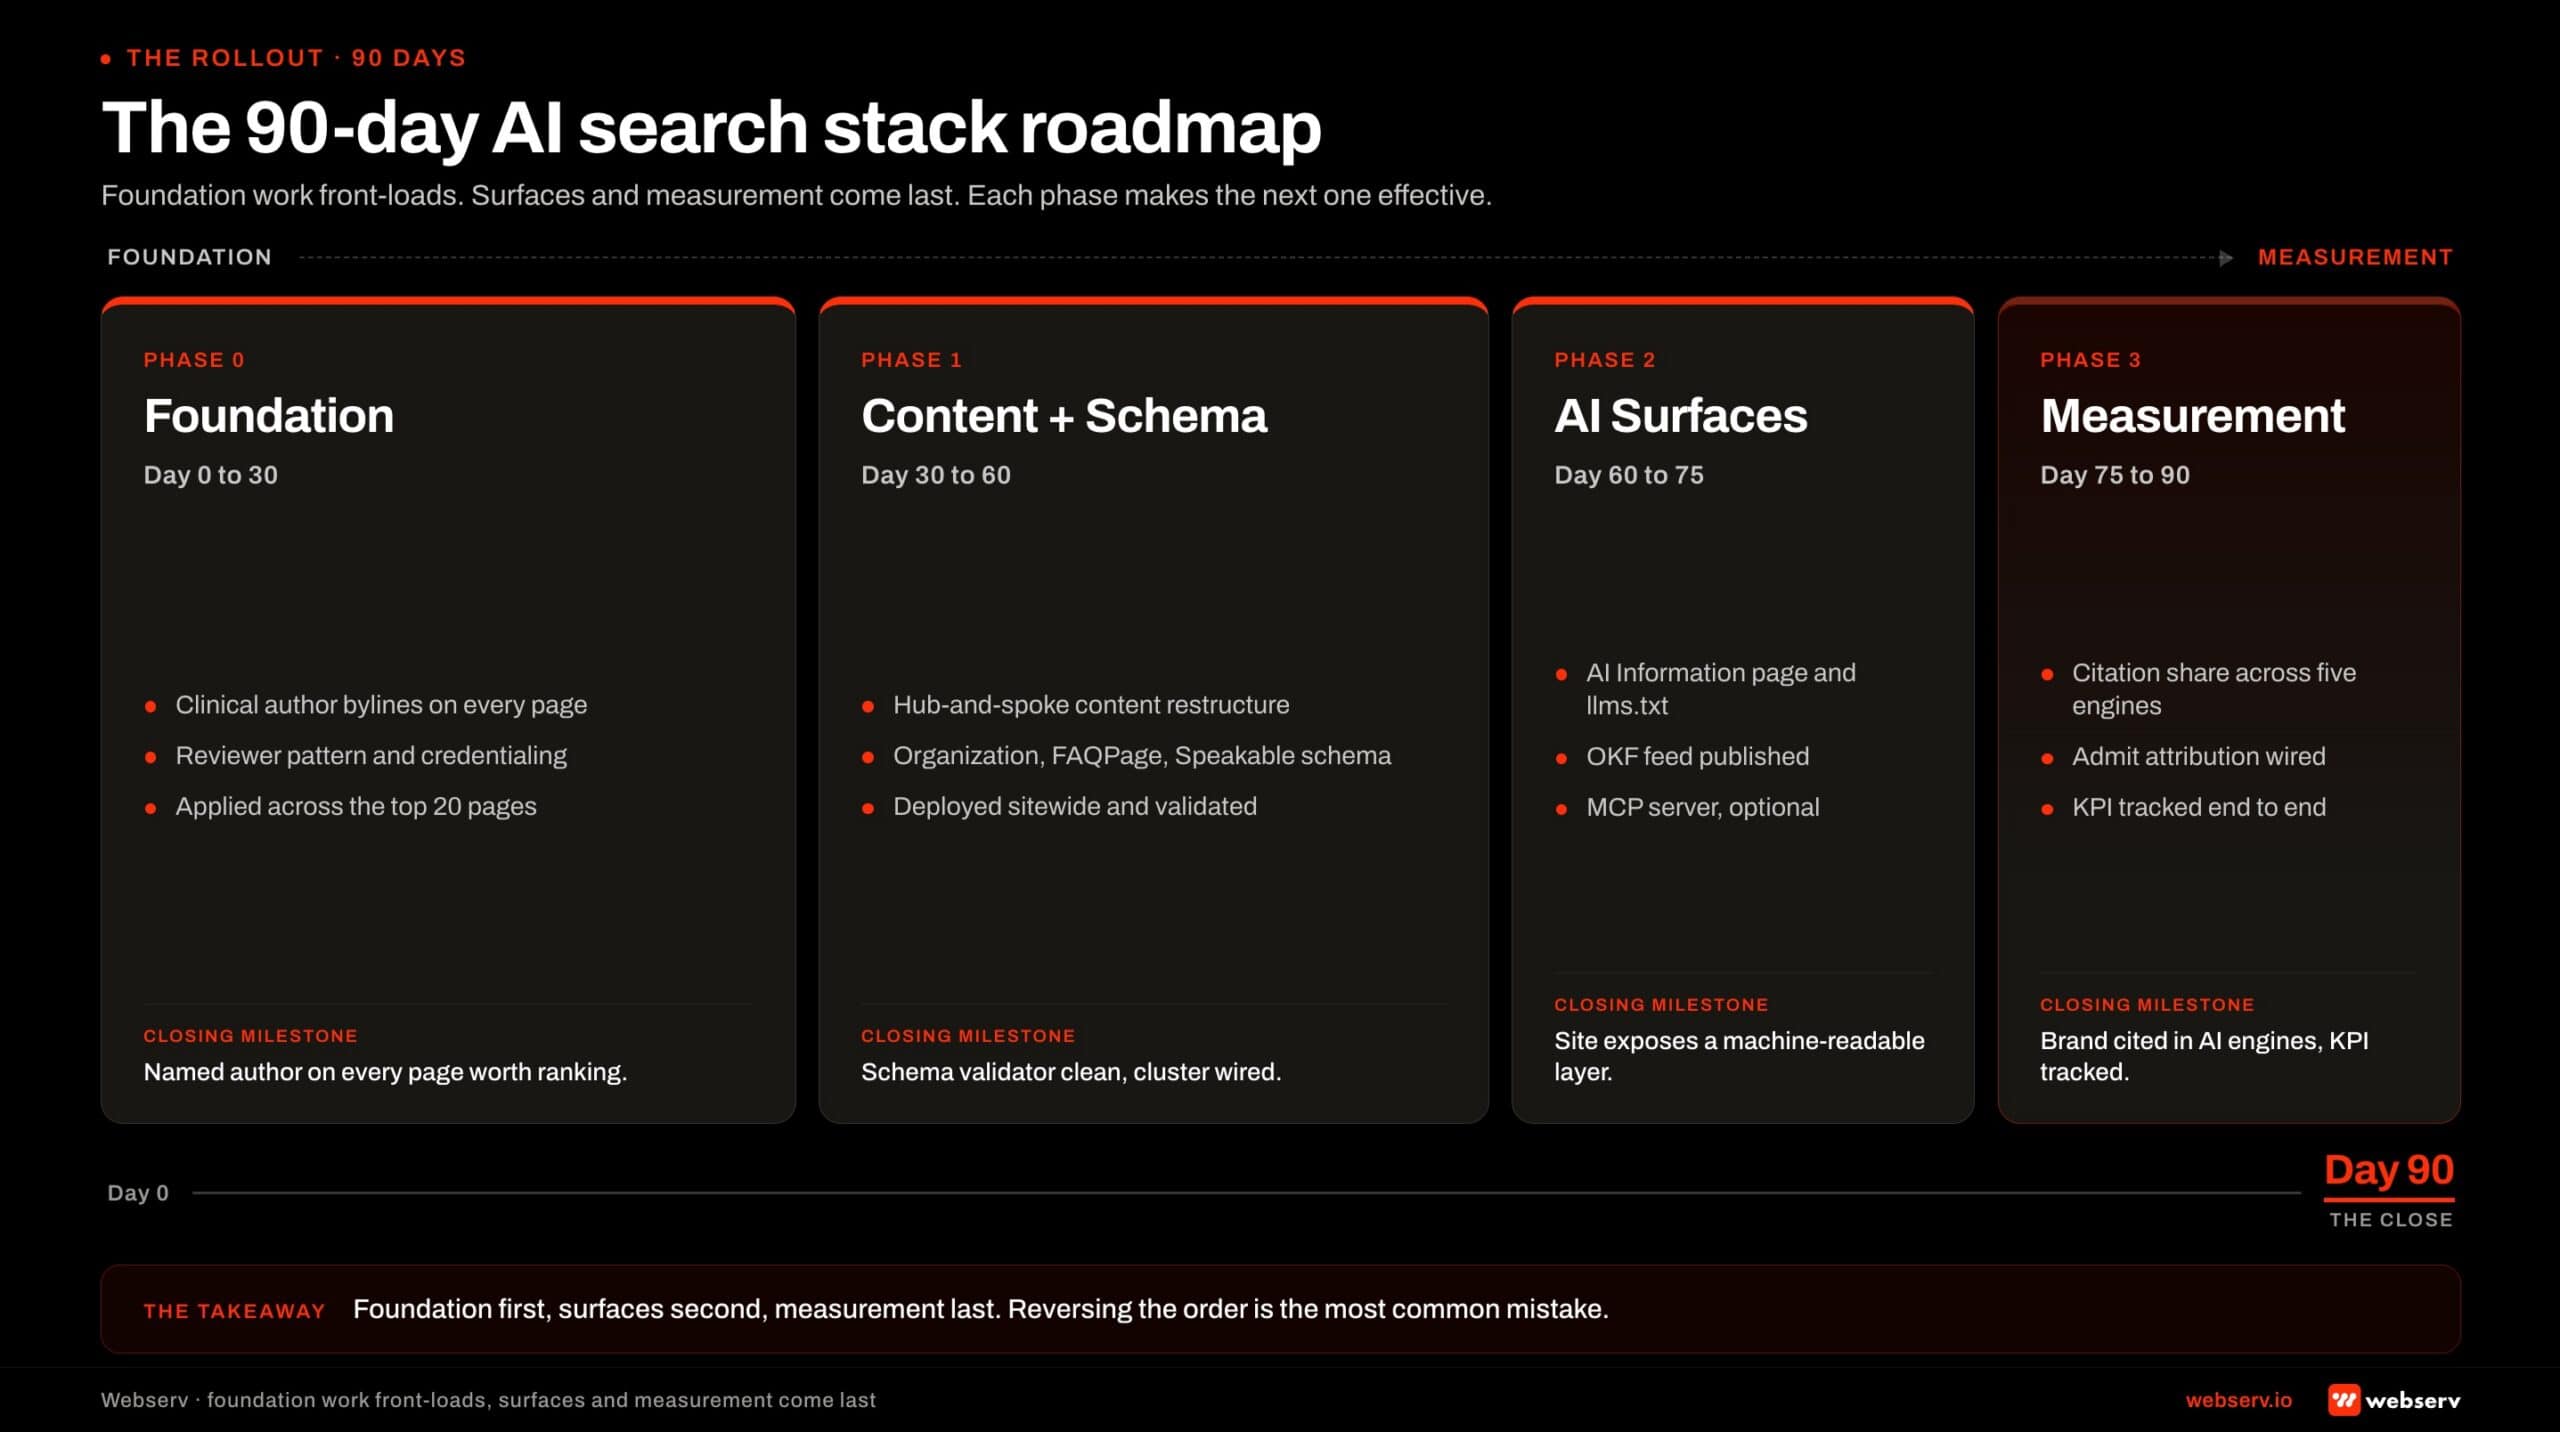 90-day implementation roadmap for the AI search stack. Phase 0 (days 0-30): foundation — clinical author bylines and reviewer pattern. Phase 1 (days 30-60): content and schema — hub-and-spoke restructure and schema deployment. Phase 2 (days 60-75): AI surfaces — AI Information page, llms.txt, OKF, MCP. Phase 3 (days 75-90): measurement — citation share tracking and admit attribution.
The operators chasing the next shiny surface (whichever AI Overview citation tactic, llms.txt prompt format, or schema variant is being discussed in newsletters this week) without the foundation underneath produce 12 months of work with no compounding signal.
If your facility is evaluating where to start on the AI search stack or wants a sanity check on a stack already in motion, book an intro meeting with the Webserv team. We will diagnose which phase is the bottleneck and walk through the sequencing that produces real lift.
Trevor Gage is the Director of Marketing at Webserv. Webserv works with behavioral health and addiction treatment centers on SEO, paid media, and full-funnel admissions strategy.